


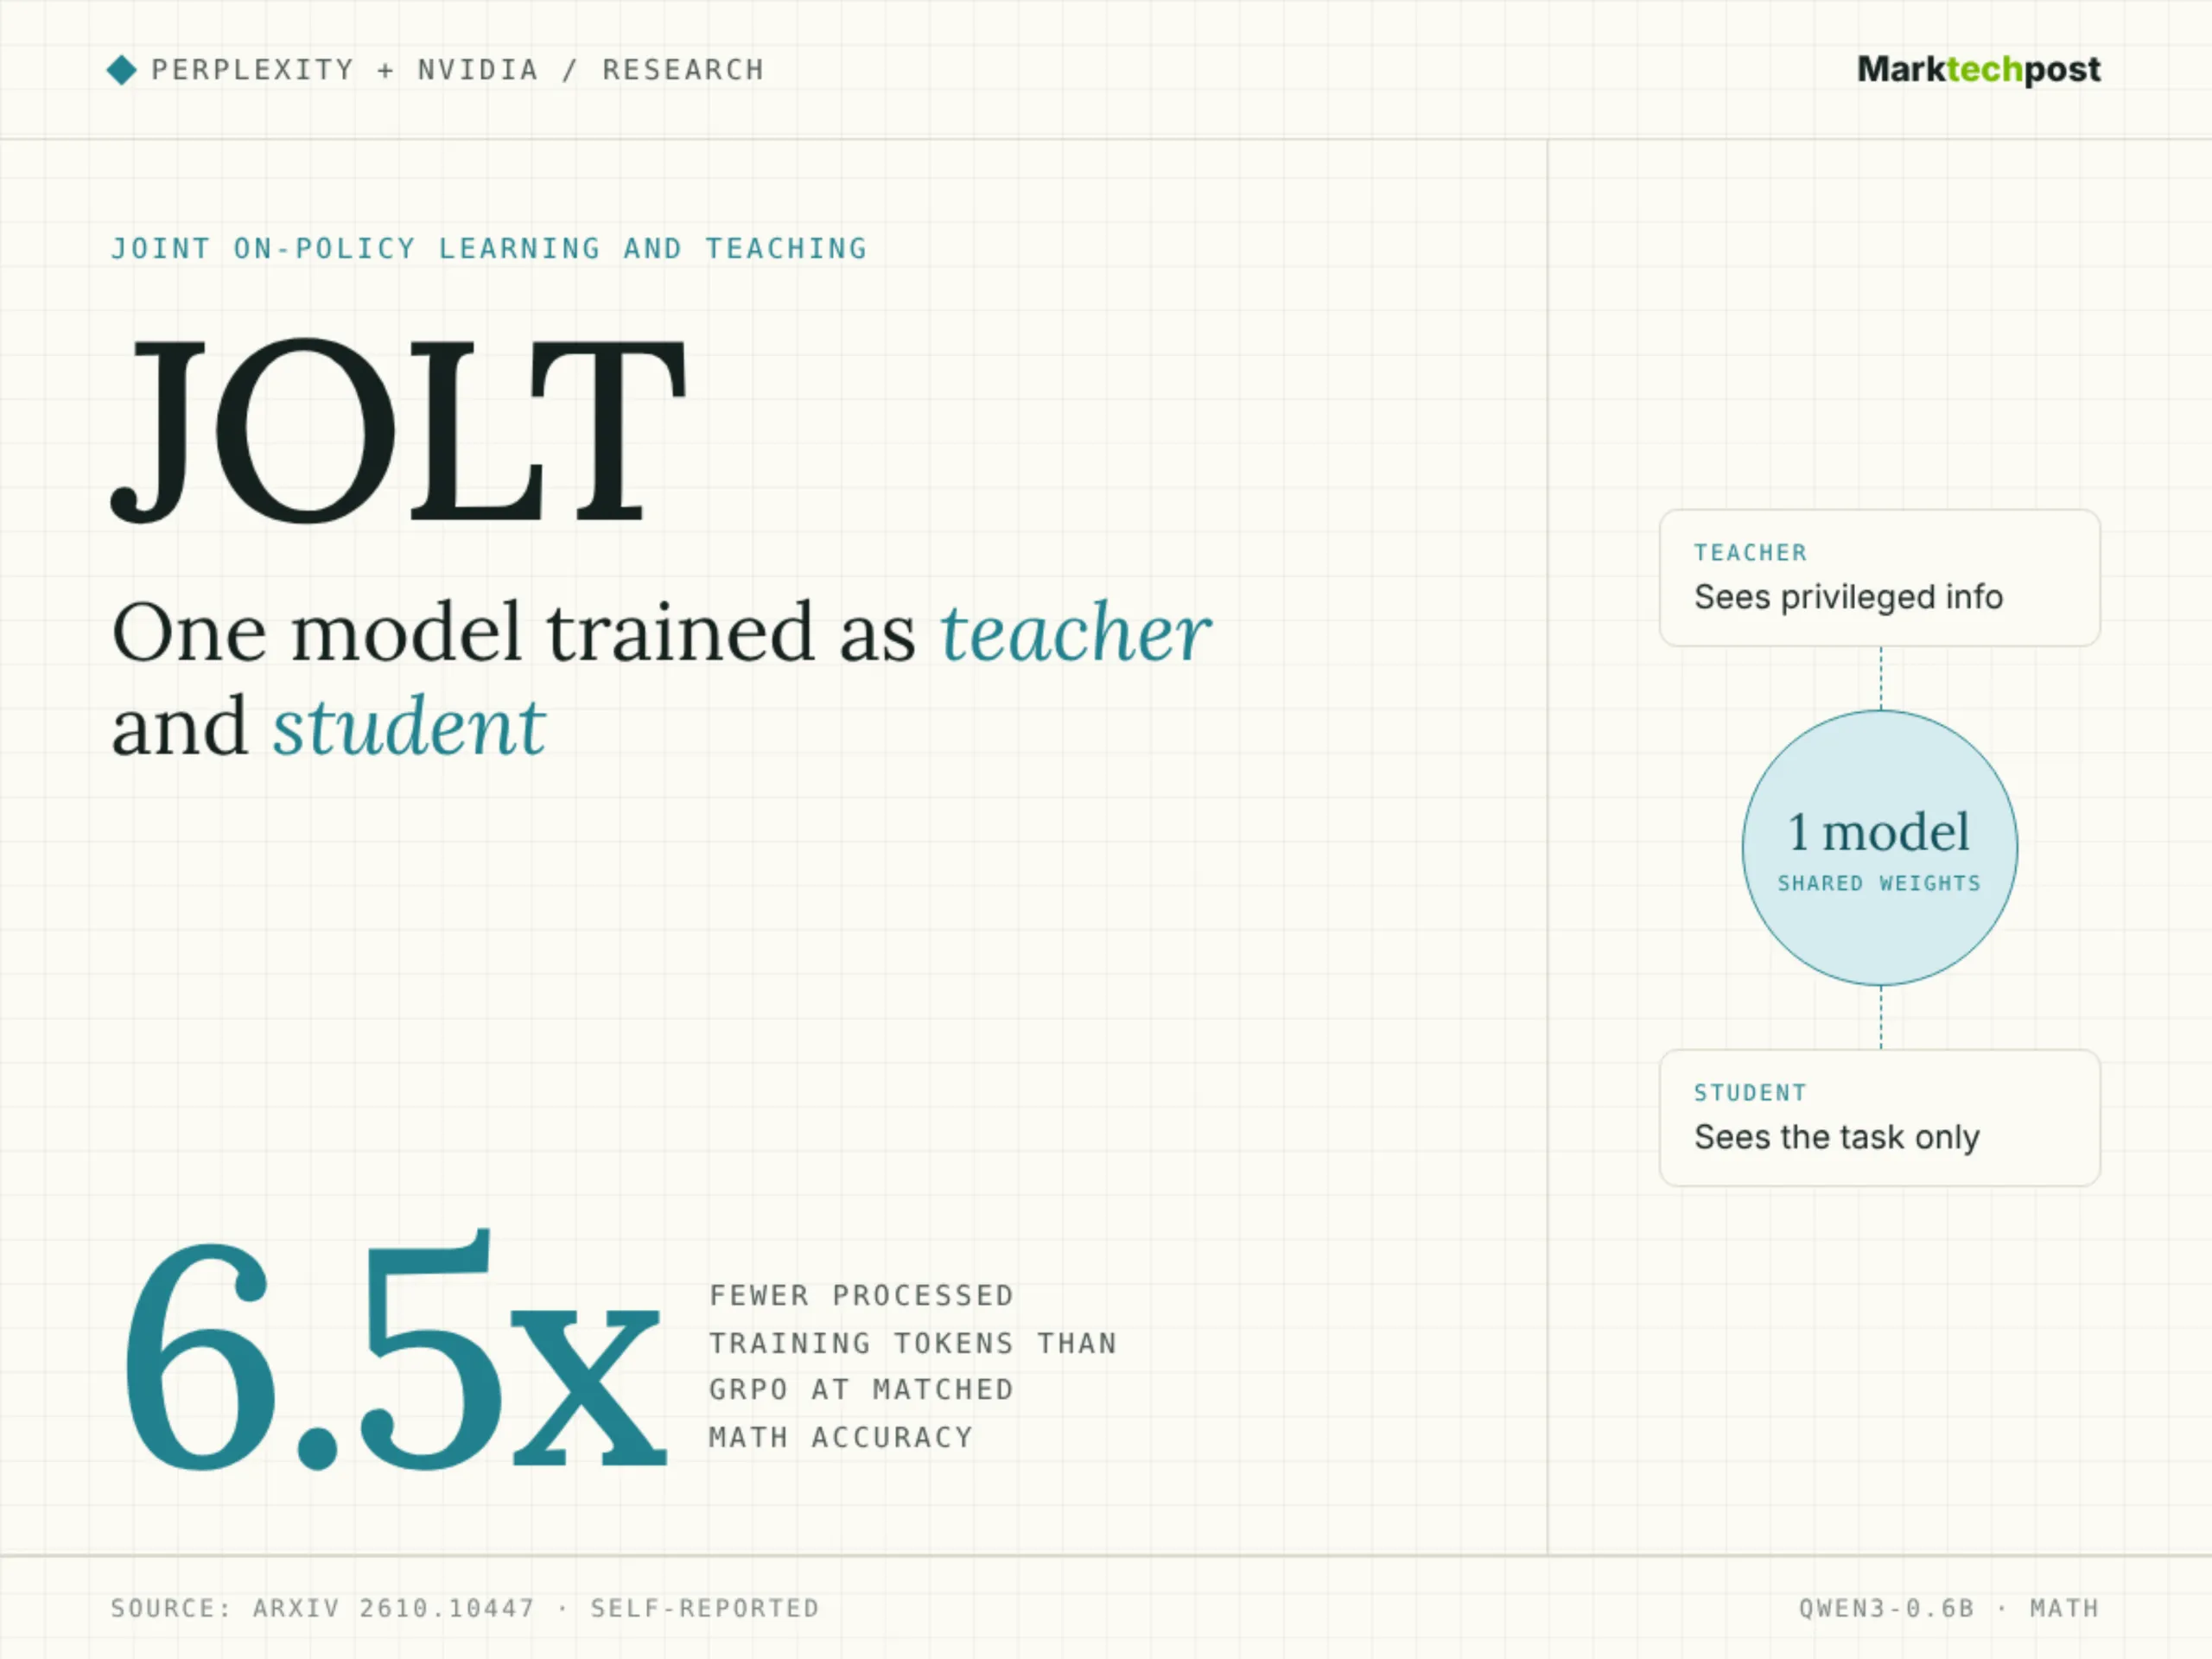
Perplexity, along with NVIDIA team, has introduced JOLT, a new post-training method for language models. JOLT stands for Joint On-policy Learning and Teaching. It trains a single model in 2 roles. The teacher sees privileged information; the student does not. The key change is that the teacher is trained too, so its feedback stays usable. On MATH, JOLT matched GRPO’s accuracy with 6.5x fewer processed training tokens. For teams running RL post-training, that is a direct compute question.
TL;DR
- What it is: a post-training method.
- Size: tested on Qwen3-0.6B, Qwen3-4B-Instruct, Qwen3-8B, Qwen3-30B-A3B-Instruct and DeepSeek-V2-Lite.
- Runs on: 1 shared model plays both roles, so no separate teacher model. Training hardware: Not disclosed.
- Performance: JOLT+ posts the highest mean score in every setting tested against GRPO, OPSD and π-Distill.
- Best: AppWorld state-test pass rate of 72.09% with JOLT+, vs 62.20% for GRPO (+9.9 points).
- Worst: JOLT without student reward scores 51.92% on AppWorld, below GRPO.
What is Perplexity JOLT?
JOLT is a self-distillation method from Perplexity and NVIDIA that trains one model as teacher and student. It builds on On-Policy Self-Distillation (OPSD).
Why does RL post-training need a better teacher?
Outcome-reward RL, such as GRPO, gives one reward per attempt. That signal is sparse. It does not say which tokens helped. On long agentic tasks, successes are rare, so learning is slow.
On-Policy Distillation fixes sparsity by having a stronger teacher score each student token. OPSD removes the separate teacher. The same model becomes the teacher when given privileged context, such as a verified solution.
The research team argues this is not enough. A teacher holding the answer can take shortcuts the student cannot follow. Its guidance may sit beyond the student’s reach. In the paper, OPSD’s teacher-student disagreement grows during MATH training.
How does JOLT work?
JOLT trains both roles of one shared model at the same time:
- Teacher: gets privileged information. It learns from outcome rewards, plus a KL penalty that keeps it close to the student.
- Student: sees only the task. It learns from the teacher’s token-level distillation signal on its own attempts.
- On-policy: each role learns from trajectories generated under its own context.
- JOLT+: adds the student’s own outcome reward to the student update.
The research stands in the center on a ‘reward-consistent’ teacher. Its distillation update should point the same way as the student’s reward gradient. The ideal teacher favors high-advantage actions while staying near the student’s policy.
‘;});
$(‘#mtpj-bars’).innerHTML=h;$(‘#mtpj-bnote’).textContent=o.n;
requestAnimationFrame(function(){requestAnimationFrame(function(){$$(‘#mtpj-bars .fill’).forEach(function(f){f.style.width=f.dataset.w+’%’;});});});setTimeout(rs,60);}
$$(‘#mtpj-seg .btn’).forEach(function(b){b.addEventListener(‘click’,function(){$$(‘#mtpj-seg .btn’).forEach(function(x){x.classList.remove(‘on’)});b.classList.add(‘on’);drawB(b.dataset.b);});});
/* tokens */
var T={proc:[[55,3.50,0.811,4.3],[63.44,8.40,1.30,6.5],[60,5.81,1.065,5.5],[65,10.73,1.443,7.4]],
comp:[[55,3.48,0.368,9.5],[63.44,8.04,0.617,13.0],[60,5.56,0.496,11.2],[65,9.92,0.691,14.4]]};
var order=[0,2,1,3],cnt=”proc”;
function anim(el,to,dec){var st=null,from=0;function f(ts){if(!st)st=ts;var p=Math.min((ts-st)/800,1),e=1-Math.pow(1-p,3);el.textContent=(from+(to-from)*e).toFixed(dec);if(p<1)requestAnimationFrame(f);}requestAnimationFrame(f);}
function drawT(){var i=order[+$(‘#mtpj-sl’).value],r=T[cnt][i];anim($(‘#mtpj-g’),r[1],2);anim($(‘#mtpj-j’),r[2],r[2]<1?3:2);
$(‘#mtpj-r’).textContent=r[3].toFixed(1)+’x’;$(‘#mtpj-acc’).textContent=r[0]+’%’;$(‘#mtpj-tv’).textContent=r[0]+’%’+(r[0]===63.44?’ (headline)’:”);}
$(‘#mtpj-sl’).addEventListener(‘input’,drawT);
$$(‘#mtpj-cnt .btn’).forEach(function(b){b.addEventListener(‘click’,function(){$$(‘#mtpj-cnt .btn’).forEach(function(x){x.classList.remove(‘on’)});b.classList.add(‘on’);cnt=b.dataset.c;drawT();});});
/* limits */
$$(‘.li’).forEach(function(l){l.addEventListener(‘click’,function(){l.classList.toggle(‘open’);setTimeout(rs,380);});});
window.addEventListener(‘load’,rs);window.addEventListener(‘resize’,rs);setTimeout(rs,300);
})();
