


Two frontier open-weight models shipped within a day of each other this week. Z.ai released GLM-5.3-Flash, a 320B-parameter multimodal MoE model with 18B active parameters. Alibaba’s Qwen team released Qwen3.8-Flash-Next, a 125B model with 6B active parameters that previews the Qwen4 architecture.
The two teams designed these systems independently. Yet their configs read like near-copies of each other. Both use a 3:1 hybrid of linear and full attention. Both select context with a compressed indexer capped at 2048 tokens. Both widen the residual stream into 4 gated branches. Both train with the Muon optimizer, with fused parameter matrices split before orthogonalization. This article walks through the shared recipe, the one point of disagreement, and the one lab that dissents.
The Two Releases in Brief
GLM-5.3-Flash is the first natively multimodal model in the GLM-5 series, released under the MIT license on Hugging Face. Z.ai tested it anonymously as Ox Alpha on OpenRouter, where it became the most popular model of the week. It was trained on a 30T-token multimodal corpus and serves a 1M-token context window. Z.ai says it outperforms GLM-5.2 across benchmarks at one-tenth the price, while approaching Claude Opus 4.8 on coding and agentic benchmarks. List pricing is $0.15 per million input tokens and $0.50 per million output tokens.
Qwen3.8-Flash-Next plays the role Qwen3-Next played for Qwen3.5: an early public preview of the next architecture family. The model card lists a 125B main model plus an additional 51B n-gram embedding table, with 6B parameters activated per token. Native context is 262,144 tokens, extensible to 1M with YaRN. The Qwen team reports that training required only about one-ninth the compute of Qwen3.7-Plus. The accompanying technical report is titled “On the Design of Qwen3.8-Next Architecture: Evaluation, Efficiency, and Training Stability.”
Convergence Point 1: Three of Every Four Attention Layers Are Linear
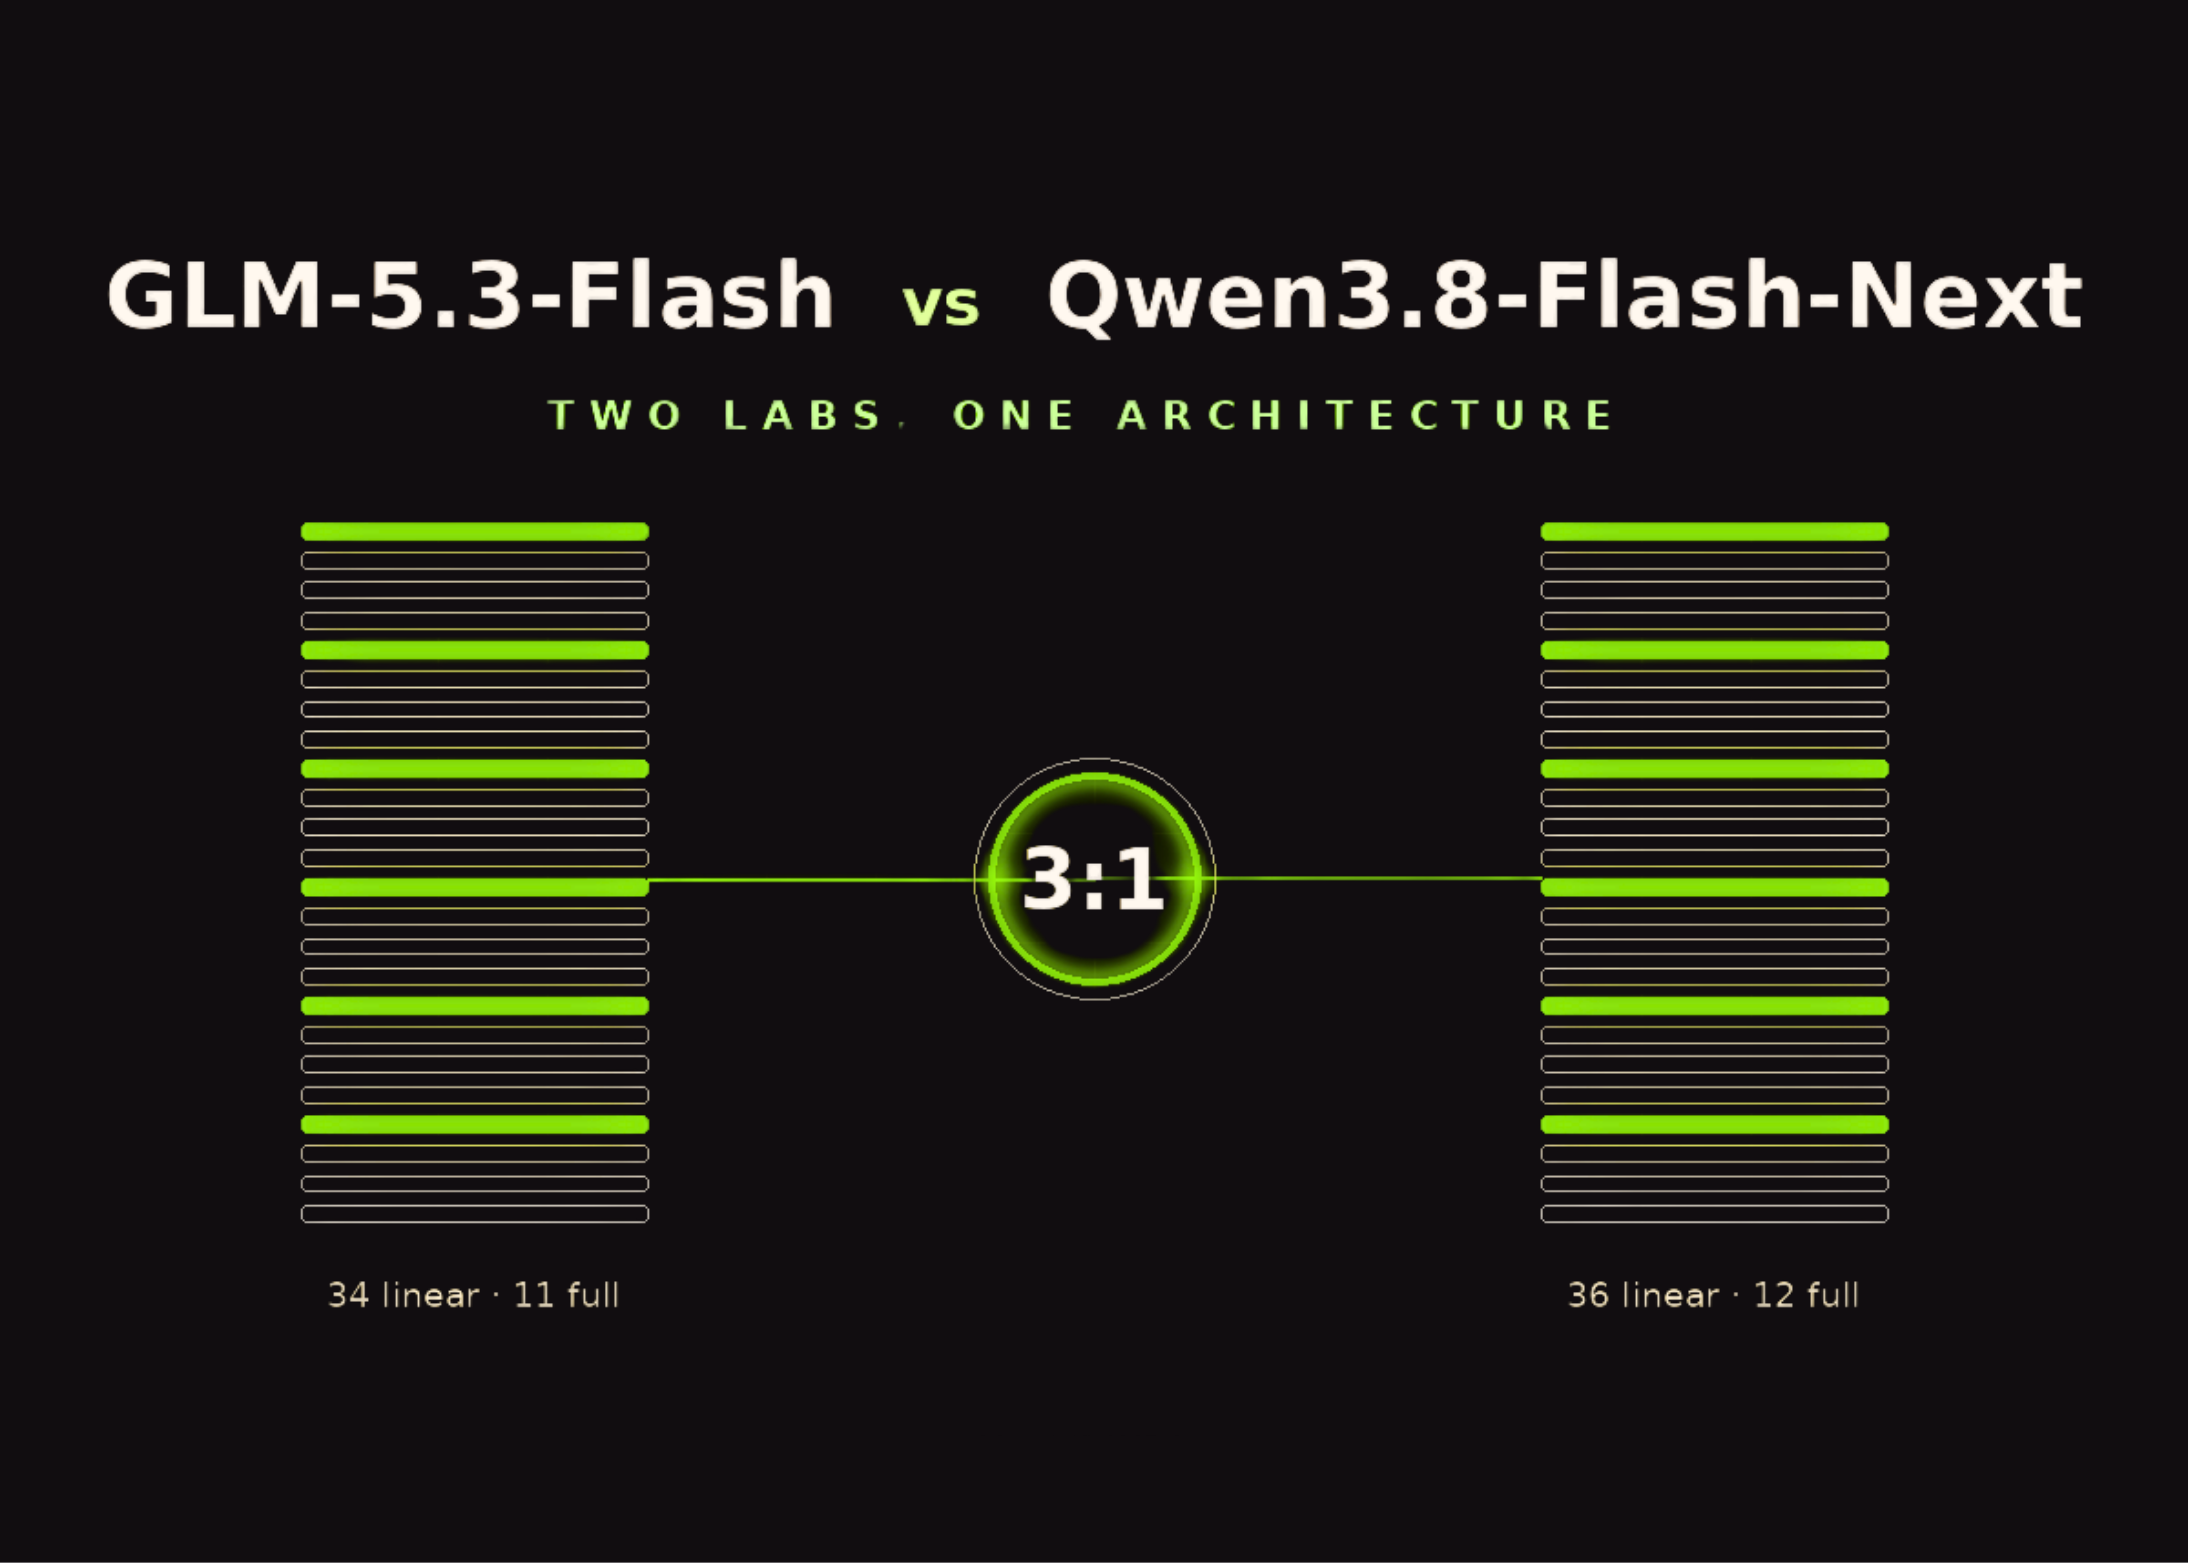
GLM-5.3-Flash stacks 45 layers: 34 linear-attention layers and 11 full-attention layers, per the shipped config. Qwen3.8-Flash-Next stacks 48 layers in a repeating block of 3 Gated DeltaNet layers plus 1 Qwen Sparse Attention layer, per the vLLM recipe. Both land on the same 3:1 ratio.
The linear layers are the cheap layers. Instead of a KV cache that grows with the text, they compress all history into a fixed-size recurrent state. Compute per token stays constant regardless of context length. GLM uses Kimi Delta Attention (KDA), the linear-attention design introduced by Moonshot AI’s Kimi Linear, which applies a fine-grained per-channel decay gate. Qwen uses its own Gated DeltaNet (GDN), which gates at the per-head level. Different gating granularity, same delta-rule family, same job.
The remaining quarter of layers do precise long-range retrieval. GLM uses NoPE multi-head latent attention (MLA) in the DeepSeek style. Qwen uses grouped-query attention inside QSA. This is where the KV cache actually lives, and where the second shared trick comes in.
Convergence Point 2: Compress 4x, Score, Keep 2048 Tokens
Neither model lets its full-attention layers attend over the entire context. Both attach a small learned indexer that scores chunks of history and keeps only the winners. The parameters match almost exactly.
GLM’s sparse layers use a 32-head lightning indexer with top-2048 selection, descended from DeepSeek’s DSA. To cut indexer cost at 1M-token contexts, Z.ai introduces IndexPool, which compresses four indexer key vectors into one through weighted pooling before scoring. Qwen’s QSA operates at micro-block granularity: the compressed lightweight indexer scores 4-token blocks and keeps the top 512 blocks, which is exactly 2048 tokens. So both models compress the context 4x before scoring, and both cap the attention budget at 2048 tokens. Qwen credits QSA with up to 7.6x prefill and 4.9x decoding speedups over full attention at 1M tokens.
The combined effect on GLM’s side is large. Compared with the full GLM-5.3 model, Z.ai reports the Flash architecture cuts attention compute by roughly 3x and KV cache size by 4.4x, while nearly halving active parameters (18B vs 32B) and layer count (45 vs 92).
Convergence Point 3: Four Residual Streams Instead of One
Both models abandon the single residual stream that has defined transformers since 2017. Both widen it into four parallel branches, with gates controlling what each block reads back and writes out.
GLM adopts Manifold-Constrained Hyper-Connections (mHC), a DeepSeek-originated design, configured with 4 branches in the shipped weights. Qwen wrote its own variant, Gated Residual, which modulates flow through 4 widened streams via an element-wise data-dependent read gate and a per-branch scalar write gate. Per the Qwen team, Gated Residual removes the extra branch-mixing step used by Hyper-Connections, reducing memory-access overhead, and the gate suppresses activation outliers well enough to allow FP8 residual storage. Notably, the Qwen team ablated both approaches and found them roughly equal in quality. Two labs, two implementations, one identical conclusion: four gated streams beat one.
Convergence Point 4: Muon, With Fused Matrices Split Per Component
Both models train with the Muon optimizer. And both apply the same subtle refinement: fused projection matrices are split into their independent transformations before Muon orthogonalizes them. Qwen documents splitting fused QKV, SwiGLU, and GDN projections, assigning Muon to genuine 2-D linear maps and AdamW to embeddings, routers, and low-rank parameters. Qwen also refit its scaling laws for the new architecture and dropped batch-size warmup entirely, after measuring that warmup cost 18.8% more optimizer steps without improving results.
Where They Disagree: Positional Encoding
The one clean split is rotary position embeddings in the full-attention layers. GLM-5.3-Flash drops them: the config sets qk_rope_head_dim = 0, making its sparse MLA layers fully NoPE. Position information flows implicitly through the recurrent linear layers.
Qwen tried the same thing and kept RoPE. According to the Qwen3.8-Next technical report, NoPE produced no measurable difference during pre-training. The failure surfaced later: after post-training, the NoPE variant often failed to stop generating. That is a useful cautionary result for the field. Pre-training loss curves can hide behavioral defects that only appear after RLHF-stage tuning.
The Broader Convergence, and the One Dissenter
This recipe is not limited to two labs. DeepSeek pioneered the sparse-indexer-plus-2048-budget pattern with DSA in DeepSeek-V3.2-Exp, and mHC is a DeepSeek design now shipping in GLM. Moonshot’s Kimi contributed KDA, the exact linear-attention layer GLM adopted. Chinese open models are visibly cross-pollinating architecture components and converging on shared settings.
The notable dissenter is MiniMax. During M2 development, the team extensively tested linear and sliding-window attention at scale and found severe deficits in multi-hop reasoning, especially beyond 32K context after SFT. M2 shipped with full softmax attention in every layer. For M3, MiniMax adopted MiniMax Sparse Attention (MSA), which sparsifies softmax attention via block selection but includes no linear-attention layers at all. So the field has not fully settled. Z.ai, Qwen, DeepSeek, and Kimi are betting that a 3:1 linear hybrid preserves reasoning. MiniMax’s ablations say it does not, at least for their stack.
Key Takeaways
- GLM-5.3-Flash (34:11) and Qwen3.8-Flash-Next (36:12) independently landed on the same 3:1 linear-to-full attention ratio.
- Both compress context 4x and cap sparse attention at a 2048-token budget, a pattern DeepSeek’s DSA started.
- Both replace the single residual stream with 4 gated branches; Qwen ablated its Gated Residual against mHC and found them equal.
- They split on positional encoding: GLM drops RoPE (NoPE), while Qwen kept it after NoPE models failed to stop generating post-training.
- MiniMax is the dissenter: its scaled ablations found linear attention hurts multi-hop reasoning, so M3 uses sparse softmax attention only.
Sources: GLM-5.3-Flash on Hugging Face, Z.ai GLM-5.3-Flash docs, GLM-5 Technical Report (arXiv:2602.15763), Qwen3.8-Flash-Next on Hugging Face, Qwen3.8-Flash-Next GitHub, NVIDIA Technical Blog, MiniMax-M2 Report (arXiv:2605.26494), and MiniMax Sparse Attention (arXiv:2606.13392)
Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
