


In the space of a month, a new category of AI model went from nonexistent to everywhere. TypeSafe AI released Jev on September 15 and called it a System One model, a nod to Kahneman’s fast, intuitive thinking. OpenAI announced its own Decisions API at DevDay and opened a public beta on October 6. Cribl published cribl-decision, an open LoRA adapter you can run locally. Others, like Laya, are already showing up in open source tooling.
These models skip text generation entirely. You hand them some state and a set of typed questions. They hand back a choice, a score, or a yes/no with a probability attached.
For security operations, I think this is some of the best news of the year. I also think most of the conversation is pointed at the wrong layer.
Why a SOC should be excited
Three properties make decision models a natural fit for alert triage.
You get a number you can automate against. A typed answer with a calibrated probability is something you can put a threshold on. Ask the model whether an alert is benign and you get back a probability. Close it automatically above 0.97. Below 0.6, treat it as a likely incident and escalate it. Anything in between goes to an analyst for a closer look. TypeSafe even suggests stricter thresholds for irreversible actions, which maps neatly onto “disable an account” versus “add a comment to the ticket.”
They’re cheap enough for every alert. Jev is priced at $42 per billion input tokens, with responses in 70 to 500 milliseconds. Say an enterprise sees 450,000 alerts a year and you feed a few thousand tokens per alert. The model bill lands somewhere around a hundred dollars a year. The economic argument for cherry-picking and only looking at high-severity alerts just disappeared!
Every verdict becomes a record. The answer space is fixed in advance and the output carries its own probability. You can log every decision, replay it, and compare it with what actually happened. That’s far easier to audit than a paragraph of generated reasoning.
One caveat worth keeping in mind. When vendors say these models “can’t hallucinate,” they mean the output always matches the schema you defined. A well-formed answer can still be wrong.
But a calibrated guess is still just a guess
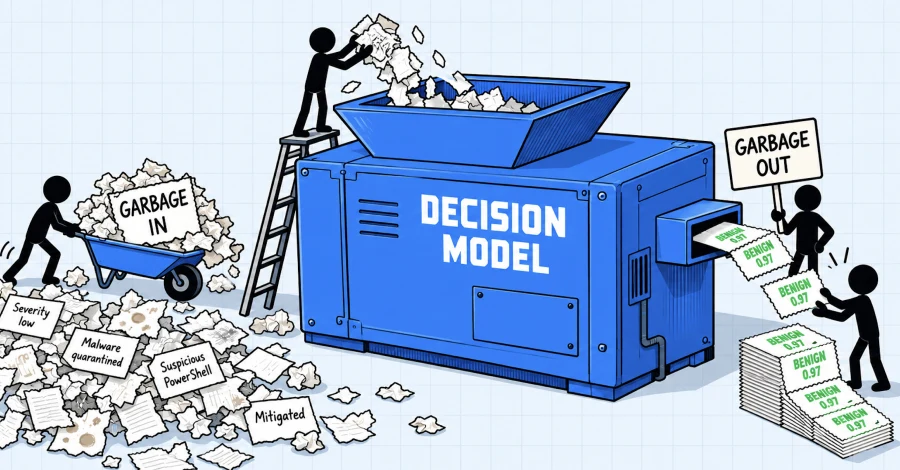
The old rule still applies. Garbage in, garbage out.
Calibration is a promise about a distribution. When a well-calibrated model says 90%, it means that across inputs that look like this one, it’s right about 90% of the time. So the question that matters is what “this one” looks like. If the input is an alert title and a severity field, the model is calibrated about alerts with that title and that severity. It knows nothing about the host.
Here’s why that matters in practice. Our AI SOC Report 2026 covers 25 million alerts triaged across our customer base in 2025. In that data, 82,000 alerts went through a live memory scan of the endpoint. About 2,600 of those machines had an active infection. And 51% of the infected machines had already been reported as mitigated by the EDR.
Think about what a decision model sees for one of those alerts. Malware detected, threat quarantined, low severity. A perfectly calibrated model should close it with high confidence, because most alerts that look like that really are fine. The model did its job. The input was wrong.
Severity has the same problem at a larger scale. Nearly 1% of real incidents in our data traced back to alerts at the lowest severity levels. At an average of 450,000 alerts a year, that’s roughly 54 real threats, about one a week.
Cribl’s own model card says it plainly. The model can be overconfident, and it’s sensitive to how the prompt and candidates are worded. That’s honest, and it applies to every model in this category.
What evidence actually looks like
Think about a crime scene. You can describe it to a chatbot in general terms and get a plausible theory. Or you can bring in the DNA lab, the fingerprints, the forensic evidence and the witness statements. Nobody needs to ask which approach finds the right suspect.
Security investigations work the same way. Filip Stojkovski recently called this Security Context Engineering, and I think the name fits. The job is to turn an alert into a set of facts before anyone, human or model, makes a call.
|
The question |
What the alert usually gives you |
What forensic evidence gives you |
|
What ran? |
“Suspicious PowerShell” |
The process tree, the parent, the full command line, the script on disk |
|
What did it do? |
A hash and a reputation score |
What the file did when detonated, the network calls, the files it dropped |
|
Is it still there? |
“Mitigated” from the EDR |
A live memory scan showing injected code or a fileless payload |
|
Who was it? |
A username |
Where they logged in, from which device, and whether that’s normal for them |
The third row deserves extra attention. The most common families we found in memory last year were tools like Mimikatz, Meterpreter and Cobalt Strike. These are built to live in memory, which is exactly where a file-based “quarantined” status can’t see.
None of this evidence is exotic. It’s what a good incident responder collects by hand. The hard part is collecting it automatically, for every alert, in under a minute.
The hardest context is what normal looks like
Forensic evidence tells you what happened on a machine. It doesn’t tell you whether that’s expected in this particular company.
Identity alerts show the gap clearly. In our 2025 data, 74% of identity alerts were classified as likely benign. Impossible travel alerts were confirmed as real compromises only about 2% of the time, and VPN usage alone drove around 30% of them. A model can’t tell that Dave from finance always logs in from Portugal, or that a CrowdStrike alert on the build servers fires every time DevOps ships a release. That knowledge usually lives in the head of your most senior analyst, and it walks out the door when they leave.
Two things make this context harder than the forensic kind. You can’t buy it, because it’s specific to your environment. And it decays, because assets, users and tooling change every week. A snapshot loaded during onboarding is stale within a quarter.
So organizational context has to be a loop. Learn from past cases and how analysts resolved them. Pull live context mid-investigation when memory isn’t enough. Then compare every verdict with its outcome and write the lesson back. That last step is also how you check whether 90% still means 90% in your environment, and not only on someone’s benchmark.
A forensic approach to alert triage and investigation
This is the layer we’ve spent our time on, so here’s a concrete example of what investing in it looks like. Our founding team came from reverse engineering and incident response, and that background shaped one rule. Collect the evidence first, then decide.
Code-level evidence. Our Genetic Analysis technology compares every piece of binary code running in memory against a large database of trusted and malicious code. It catches known malware, and it also catches new code that reuses pieces of known threats.
Live memory forensics, triggered automatically. When an alert doesn’t carry enough evidence for a verdict, or there are signs of a fileless attack or code injection, the platform runs our Endpoint Scanner on the machine. It’s a single executable with nothing to install. It collects process trees, executables loaded into memory, memory dumps where injection is suspected, and the files behind scheduled tasks and autoruns. That’s how we found the infected machines marked as mitigated.
Detonation and network forensics. Suspicious files get run in a sandbox, and URLs, domains and IPs get investigated, so the verdict rests on observed behavior.
Organizational memory. Org Brain is our answer to the “what’s normal here” problem. It keeps two kinds of memory. One is procedural, how your team investigates and which detections it closes on sight. The other is declarative, your assets, your users, their normal behavior, and even how your SIEM schema is structured. It learns from your case history, fetches live context mid-investigation, and writes conclusions back after every investigation.
All this allowed us to investigate over 25 million alerts in 2025, at every severity. Fewer than 2% were escalated to a human, verdict accuracy was 98%, and median triage time was under a minute.
When it comes to cost, most of this analysis is deterministic forensics, which is far more affordable to run than a large model on every alert. That’s why we price per endpoint and have been investigating everything, long before decision models arrived. Decision models now bring the same economics to the decision step for everyone, and that’s a good thing for the industry.
If you’re building your own pipeline, the same structure applies whichever model sits at the end. Spend your engineering effort on the evidence and the organizational knowledge. Those are the parts that are hard to get and the parts that compound.
Where to put your effort
Frontier models get better every few months, and everyone gets the upgrade on the same day. Decision models will follow the same curve. Whatever edge a model gives you this quarter, your competitors and your attackers have it too.
The context you feed those models is the part that’s actually yours. If you’re automating triage this year, here’s where I’d spend the time.
- Collect evidence before you decide. Process trees, detonation results and memory contents beat alert metadata every time.
- Stop letting severity decide what gets investigated. With decision models this cheap, there’s no longer a cost reason to skip low-severity alerts.
- Treat organizational knowledge as a system. Assets, users and normal behavior need to be learned and refreshed continuously.
- Measure calibration in your own environment. Tie every automated verdict to its outcome, and watch for drift.
Decision models make the last step fast, cheap and auditable. Whether that last step is right still depends on everything that came before it.
