

Close Menu
NCIJ Network NCIJ Network
    What's Hot

    Badenoch returns to Conservative conference much stronger than a year ago | Kemi Badenoch

    October 3, 2026

    3D movies are finally worth watching

    October 3, 2026

    Circle Pushes Back on MiCA’s Bank-Deposit Mandate for Stablecoins

    October 3, 2026
    Facebook X (Twitter) Instagram
    Trending
    • Badenoch returns to Conservative conference much stronger than a year ago | Kemi Badenoch
    • 3D movies are finally worth watching
    • Circle Pushes Back on MiCA’s Bank-Deposit Mandate for Stablecoins
    • Leucine does more than build muscle. It powers up your cells
    • Our Future Might Be Darker—and That’s a Good Thing
    • At least a dozen graves of Milwaukee Indian boarding school students uncovered
    • The expansion of Heathrow would be an expensive disaster for Britain and the world. Burnham needs to block it | George Monbiot
    • Barricades & the blame game: the French school protests – The World This Week
    • About
      • Our Team
      • Editorial Policy
      • Editorial Independence
      • International Support
    • Trust & Standards
      • AI Usage Policy
      • Conflict of Interest Policy
      • Corrections Policy
      • Ethics Policy
      • Fact-Checking Policy
      • Source Protection
    • Get Involved
      • Guide for Sources
      • Support Independent Journalism
    • Legal
      • Cookie Policy
      • Privacy Policy
      • Terms of Use
    Facebook X (Twitter) Instagram
    NCIJ Network NCIJ Network
    Saturday, October 3
    • Home
    • World
    • Ai
    • Business
    • Politics
    • Health
    • Crypto
    • Science
    • Technology
    • Cybersecurity
    • Defense & Security
    • Economy
    • Energy
    • Europe
    • More
      • Fact Check
      • Investigations
      • Opinion & Analysis
      • Environment
    NCIJ Network NCIJ Network
    Home»Artificial Intelligence

    Prime Intellect Launches Prime Inference: Serverless and Reserved Serving for Frontier Open Models

    NCIJ NETWNCIJ NETWORKBy NCIJ NETWNCIJ NETWORKOctober 3, 2026 Artificial Intelligence No Comments4 Mins Read
    Share
    Facebook Twitter LinkedIn Pinterest Email

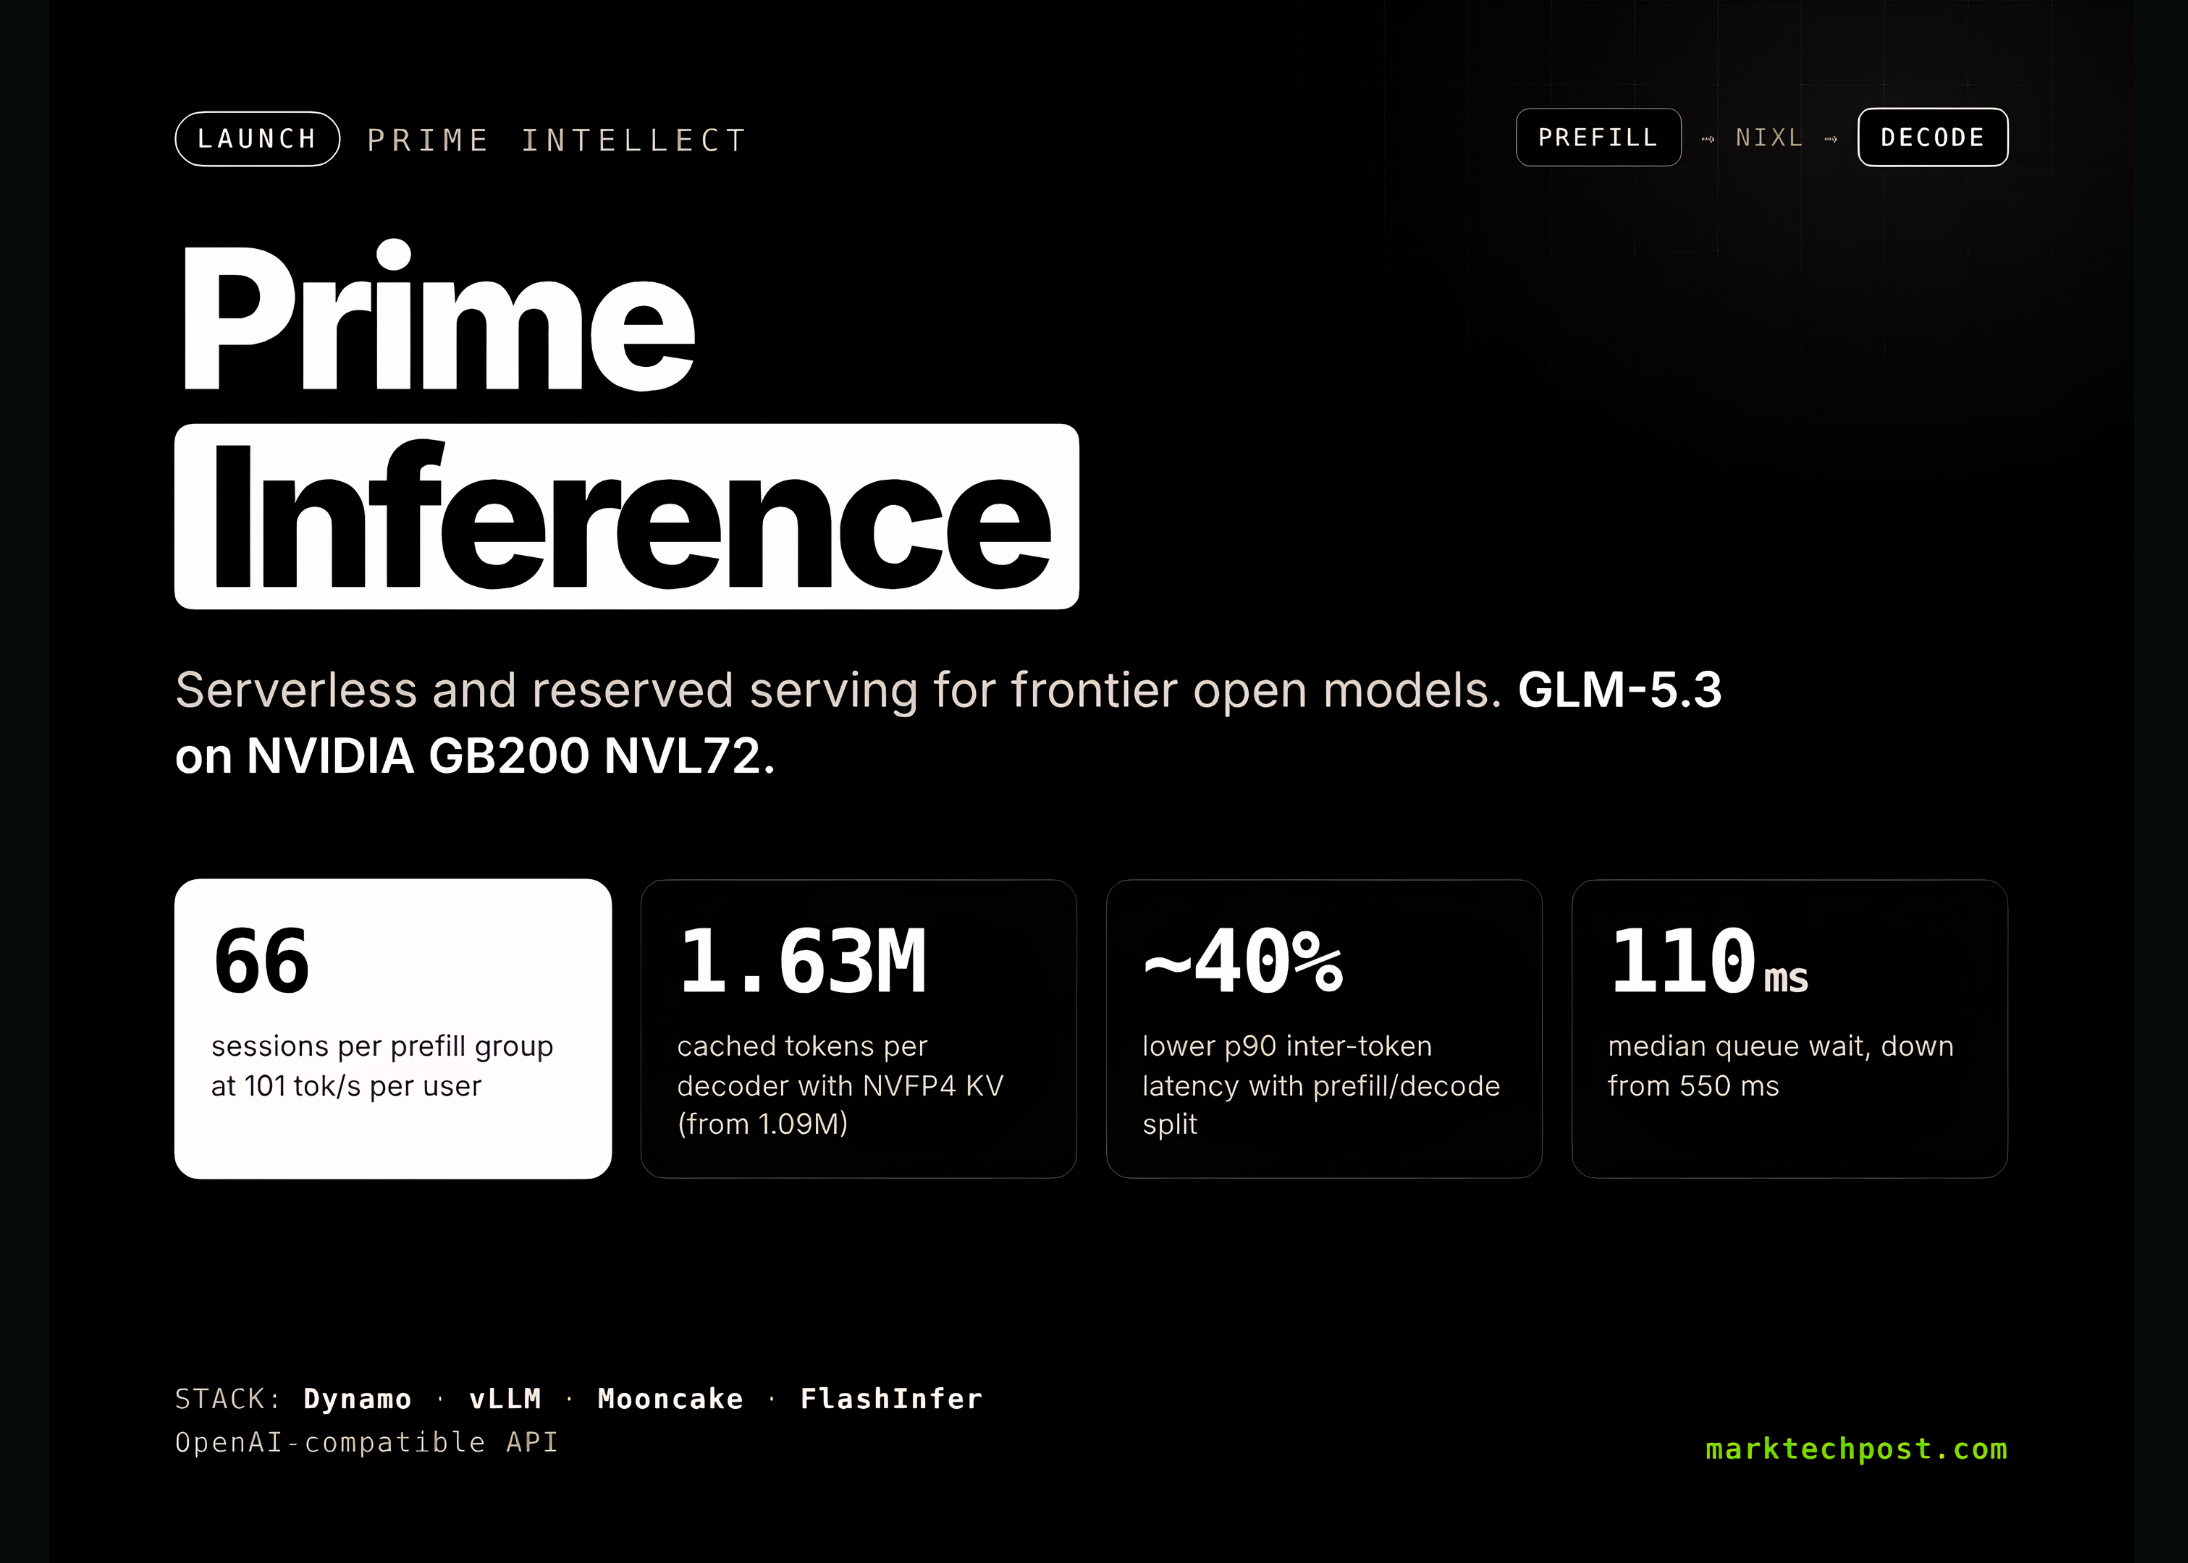
    Prime Intellect has launched Prime Inference, a serving platform for frontier open-source models. It offers serverless endpoints and reserved capacity on Prime’s own GPUs across multiple datacenters. Before public release, it processed nearly a trillion tokens per day internally. That traffic came from RL rollouts, synthetic data generation, evaluations and long-running coding agents.

    What is Prime Inference?

    Prime Inference is the serving layer of Prime Intellect’s open training stack. The company already ships post-training tools such as prime-rl, verifiers and sandboxes. Serving closes that loop: deployed models generate production traces that can feed back into training. Prime reports its GLM-5.3 endpoint ranks among the fastest on OpenRouter. It also cites a near-zero tool-call error rate and 100% uptime since launch.

    • Two modes: serverless endpoints for variable demand, reserved capacity for sustained workloads.
    • OpenAI compatible: point any OpenAI SDK at https://api.pinference.ai/api/v1 (docs).
    • Uptime: automatic failover across datacenters routes traffic to healthy deployments.
    • Hardware: NVIDIA Blackwell today, with Vera Rubin listed as coming soon.
    • Billing: unified billing with team-level usage tracking. Per-model pricing is not yet fully published in the docs.

    How the serving stack works

    The stack combines NVIDIA Dynamo, vLLM, Mooncake and FlashInfer. It was built with Inferact and NVIDIA, and fixes are contributed upstream.

    The target workload is agentic. A typical agent turn adds about 6K tokens to a 140K-token prompt. Prime benchmarks this mix with SemiAnalysis AgentX, and injected cold arrivals.

    Prefill/decode disaggregation: Prefill and decode run on separate GPU groups. Dynamo handles routing, and vLLM runs the model on each group. Decoders pull computed KV through NIXL. Prime reports nearly 40% lower p90 inter-token latency in its tests.

    Cache-aware routing:Dynamo’s KV-aware router weighs cached prefix overlap against queued work. Sessions stay on the same decoder between turns. Mooncake adds a second KV tier in host DRAM.

    GLM-5.3 on GB200 NVL72: the numbers

    The interactivity target was 100 end-to-end tokens per second per user. At that bar, a 1:4 prefill/decode ratio served the most users. It reached 66 sessions per prefill group at 101 tok/s per user and 100 output tok/s per GPU.

    • DEP8 prefill topology: roughly 5x more usable prefix-cache capacity than TEP8 on the same hardware.
    • Smaller prefill budget: halving tokens per step from 8K to 4K per GPU cut median queue wait from 550 ms to 110 ms. Median time to first token fell about 20%.
    • NVFP4 KV compression: each MLA cache row shrank from 576 to 352 bytes. Cached tokens per decoder rose from 1.09M to 1.63M.
    • Native sparse-MLA kernel: about 12.0 μs at 15 query tokens, versus 17.7 μs staged and 13.7 μs FP8. Prime notes this is workload specific.
    • BLHNC KV layout: transfer descriptors fell from 19,559 to about 1,940. Mean transfer time dropped from 146 ms to 78 ms.

    Agents fail when tool calls carry wrong names or broken arguments. Prime Intellect’s team contributed a structural-tag builder to Dynamo for GLM’s tool format. vLLM then uses xgrammar to mask tokens that violate the tool schema. The team also fixed parsing bugs, including < being decoded into < inside code.

    Interactive explainer

    Frontier Inference Intellect Launches models open Prime Reserved Serverless Serving
    NCIJ NETWNCIJ NETWORK
    • Website

    Keep Reading

    Meta, OpenAI and Uber Just Taught AI Agents to Talk First. What About When to Stay Quiet?

    IBM Brings Bob to Self-Hosted and Air-Gapped Environments: Agentic Software Development Without Moving Your Code

    California Subpoenas OpenAI Over AI Models That Hacked Their Way Out of a Test

    Decision AI Models Explained: TypeSafe Jev vs Fastino GLiDE, GLiNER2.5-Decide and Open-Source Competitors

    NVIDIA Announces DGX Spark 64GB: A 1-PetaFLOP Grace Blackwell Desktop for Local AI Agents, Fine-Tuning, and Inference

    Datalab Introduces OmniExtractBench to Fix Bias and Opacity in Extraction Benchmarks

    Add A Comment
    Leave A Reply Cancel Reply

    Editors Picks

    Badenoch returns to Conservative conference much stronger than a year ago | Kemi Badenoch

    October 3, 2026

    3D movies are finally worth watching

    October 3, 2026

    Circle Pushes Back on MiCA’s Bank-Deposit Mandate for Stablecoins

    October 3, 2026

    Leucine does more than build muscle. It powers up your cells

    October 3, 2026
    Latest Posts

    Lime bikes hurtling around the city: is this the revenge of a priced-out generation? | Andy Beckett

    August 8, 2026

    Clarity Act Delayed Until September, Trump Praises Bitcoin

    August 8, 2026

    North Carolina Ports confirms cyberattack disrupting operations

    August 8, 2026

    Subscribe to News

    Get the latest sports news from NewsSite about world, sports and politics.

    NCIJ Network is an independent digital news platform delivering trusted investigative journalism, European and global news, in-depth analysis, and fact-based reporting with accuracy, transparency, and integrity.

    Facebook X (Twitter) Instagram Pinterest YouTube

    Badenoch returns to Conservative conference much stronger than a year ago | Kemi Badenoch

    October 3, 2026

    3D movies are finally worth watching

    October 3, 2026

    Circle Pushes Back on MiCA’s Bank-Deposit Mandate for Stablecoins

    October 3, 2026

    Subscribe to Updates

    Get the latest creative news from FooBar about art, design and business.

    Type above and press Enter to search. Press Esc to cancel.