


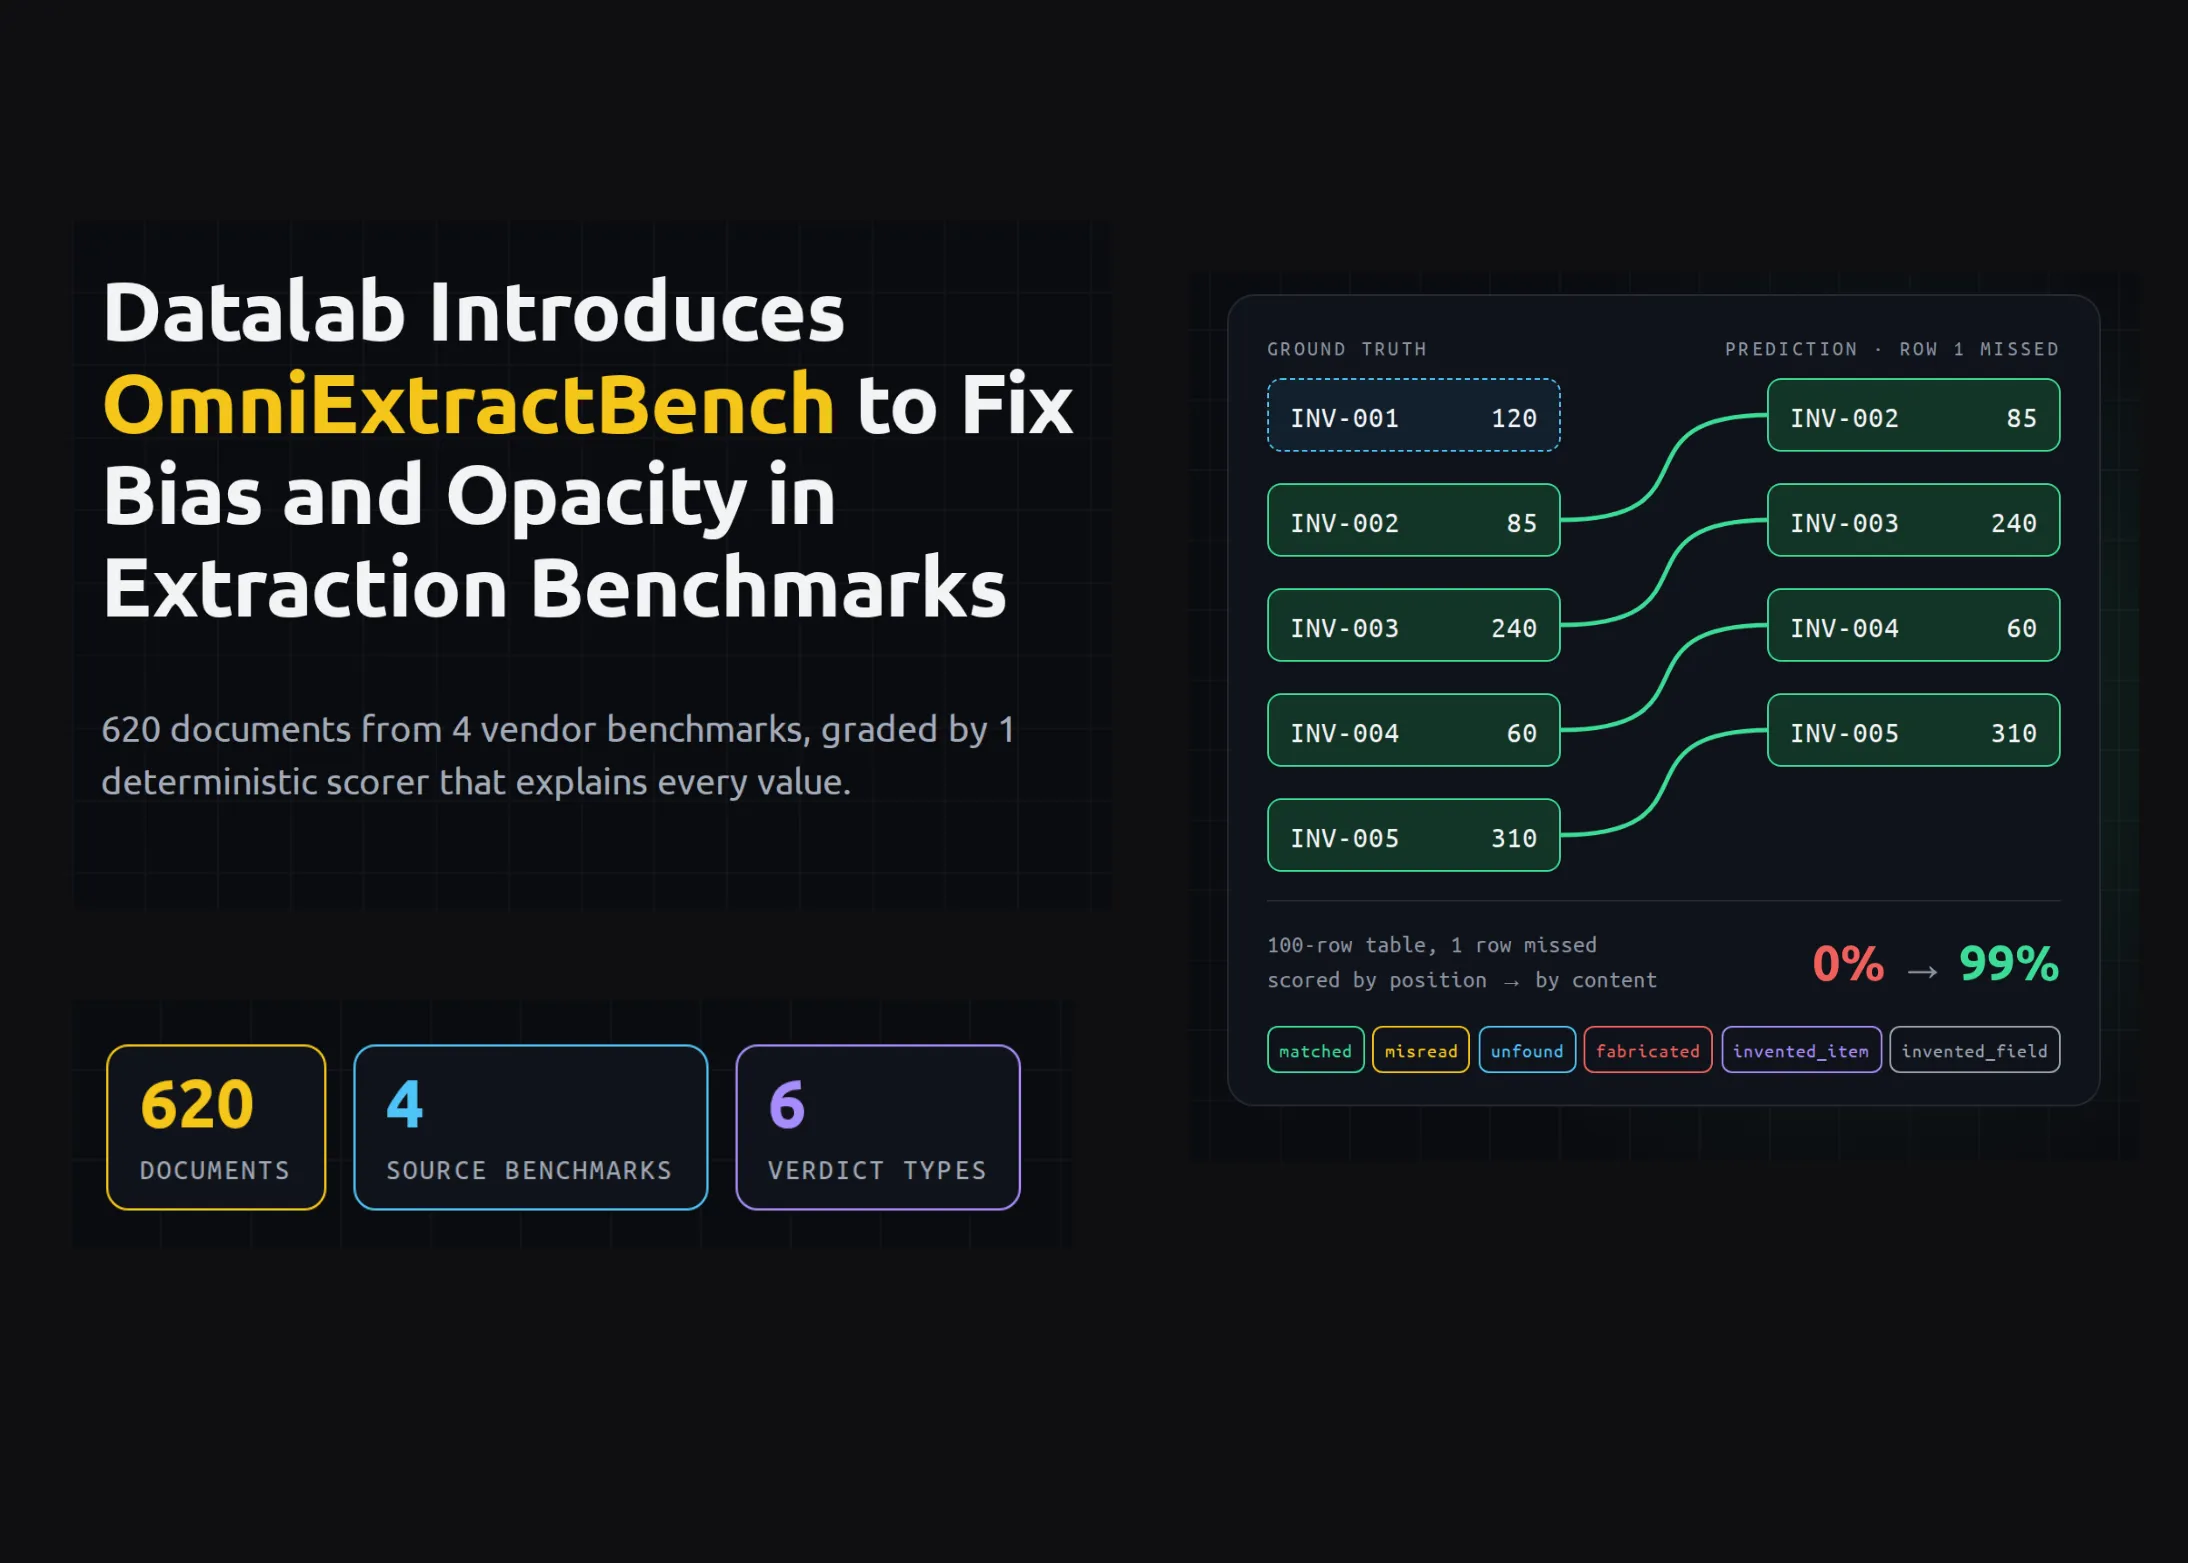
Datalab has released OmniExtractBench, an open benchmark for structured document extraction. It tests how accurately a system fills a JSON schema from a PDF. The benchmark pools 620 documents from 4 existing benchmarks. One deterministic scorer grades all of them and explains each decision.
The release lands while extraction vendors publish their own leaderboards. Datalab argues those leaderboards are hard to compare or audit. OmniExtractBench is its attempt at a shared yardstick.
Is it deployable? Yes, the scorer installs from PyPI as omni-extract-bench (v0.1.7, Python 3.11+, SciPy only) under Apache 2.0. Rerunning vendors requires your own API keys and paid credits.
OmniExtractBench is a structured extraction benchmark built by Datalab. Each task gives a system a PDF and a JSON schema. The system returns JSON, which is scored value by value against a gold file. The code is on GitHub, and the data is on Hugging Face under CC BY 4.0.
The 4 flaws it targets
Datalab’s launch post names 4 recurring problems with existing extraction benchmarks:
- Bias: documents and scoring can favor the vendor that built the benchmark.
- Opaque harnesses: a low score may reflect a broken harness, not a weak model.
- Unclear scoring: readers cannot tell why a given document scored low.
- Narrow document variety: some suites hold only dense tables, others only clean, unscanned files.
Where the 620 documents come from
| Suite | Documents | Upstream publisher | Content |
| ExtractBench | 329 | LlamaIndex | Forms, filings, decks |
| Internal | 202 | Datalab (synthetic) | Dense scalar schemas, small documents |
| LongExtractBench | 47 | micro1 (commissioned by Reducto) | Very large tables |
| LongArray-Extract | 42 | Extend | Large tables with repeated scalars |
Regulatory filing forms are the largest category, at 88 documents. 128 documents are a single page. At the other end, 33 documents over 100 pages hold 40% of all pages. Datalab’s own synthetic suite is the second largest share.
How the scorer works
The scorer flattens prediction and gold JSON into addresses, which are paths to single values. It normalizes each value first, so “03/31/2024” matches “2024-03-31”.
Tables are the hard part. Compared by position, one missed row shifts every row after it. We reran the scorer on a 100-row table missing its first row. Positional comparison scored 0%, while OmniExtractBench scored 99%.
The fix is content-based pairing with the Hungarian algorithm. ExtractBench and LongArray-Extract already align rows this way. OmniExtractBench adds a verdict layer on top.
6 verdicts per value
- matched: paired, and the values agree.
- misread: paired, but the values differ.
- unfound: gold has a value, the prediction does not.
- fabricated: the schema allows it, gold is silent, the prediction fills it.
- invented_item: part of a predicted row that pairs with nothing.
- invented_field: an address the schema never declared.
Accuracy is matched values over all verdicts. Precision divides matched values by predicted values. Recall divides them by gold values. The full rules are in the metric spec.
The null rule
Empty strings, None and whitespace count as omissions, so those addresses are dropped. Strings like “NA” or “-” remain real answers. This blocks a quiet exploit: padding a schema with empty optional fields to earn free matches. In our test, padded null fields added 0 verdicts.
| Benchmark | Publisher | Documents | Row alignment | Per-value explanation | Scorer license | Data license |
| OmniExtractBench | Datalab | 620, from 4 sources | Hungarian, by content | Yes, 6 verdict types | Apache 2.0 | CC BY 4.0 |
| ExtractBench | LlamaIndex | 370 | Hungarian | Per-field diffs, HTML report | Apache 2.0 | Apache 2.0 |
| LongArray-Extract | Extend | 45, synthetic | Hungarian | Per-document score | Not stated | CC BY 4.0 |
| LongExtractBench | micro1 | 225, of which 50 public | By row key | Not stated | MIT | CC BY 4.0, labels only |
Sources linked on each benchmark name. Checked September 27, 2026.
Who misses fields and who invents values
Datalab scored 10 system configurations on the full corpus. Its accurate mode led at 93.85 accuracy. Datalab balanced (93.48) and Reducto deep_extract v2 (93.47) are effectively tied. Precision and recall then show how each system fails.
- Balanced: Datalab (both modes) and Reducto keep precision and recall within 0.6 points.
- Leans to misses: GPT 5.6-sol posts 95.11 precision but 84.99 recall. It loses 11.88% to unfound values. Gemini and Claude show the same pattern, less sharply.
- Leans to invented values: LlamaExtract has 93.13 recall but 86.57 precision, losing 9.03% to fabricated values. Extend loses 4.01% to invented items.
- Low on both: Mistral OCR 4.1 and Azure Content Understanding trail on both metrics, with recall lower still.
How each system falls short of 100%, by verdict type. Source: Datalab.
Run it yourself
uv pip install omni-extract-bench
oeb score --pred pred.json --gt gold.json --schema schema.json --verdicts
Install the [benchmark] extra and run oeb benchmark to rerun vendors. Runs are resumable, and each provider needs its own credentials. Datalab also suggests testing its playground on your own documents.
Key Takeaways
- OmniExtractBench pools 620 documents from LlamaIndex, micro1, Extend and Datalab suites.
- A deterministic scorer gives every value 1 of 6 auditable verdicts.
- Content-based row pairing stops one missed row from zeroing a table.
- Dropping null addresses stops schema padding from inflating scores.
- Datalab accurate leads at 93.85; Datalab balanced and Reducto tie near 93.5.
FAQ
- What does OmniExtractBench measure? It measures how accurately a system extracts values from a PDF into a JSON schema, scored per value.
- Is OmniExtractBench open source? Yes. The scorer is Apache 2.0 on GitHub and PyPI. The dataset is CC BY 4.0 on Hugging Face.
- Who built OmniExtractBench? Datalab built it. Datalab also maintains the open-source Marker and Surya document tools.
Thanks to the Datalab team for the resources behind this article. Datalab supported and sponsored this content.
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
