

Close Menu
NCIJ Network NCIJ Network
    What's Hot

    IBM AI Releases Granite Speech 5.0 2B for Multilingual Transcription and Translation

    October 22, 2026

    Authorities disrupt nearly 11,000 cybercrime networks in Africa

    October 22, 2026

    Fires Char New Guinea – NASA Science

    October 22, 2026
    Facebook X (Twitter) Instagram
    Trending
    • IBM AI Releases Granite Speech 5.0 2B for Multilingual Transcription and Translation
    • Authorities disrupt nearly 11,000 cybercrime networks in Africa
    • Fires Char New Guinea – NASA Science
    • Li Qiang and Cai Qi Are Xi Jinping’s Soldiers, Not Successors
    • Viral clip shows Bangladesh coast not ships stuck in Strait of Hormuz – Full Fact
    • Murder arrest over death of Jacqueline Causton in Zante
    • Angry scenes at Senedd as Reform call for ban on Muslim face coverings
    • The ‘trillion pound’ oil fund the government believes Britain could have built
    • About
      • Our Team
      • Editorial Policy
      • Editorial Independence
      • International Support
    • Trust & Standards
      • AI Usage Policy
      • Conflict of Interest Policy
      • Corrections Policy
      • Ethics Policy
      • Fact-Checking Policy
      • Source Protection
    • Get Involved
      • Guide for Sources
      • Support Independent Journalism
    • Legal
      • Cookie Policy
      • Privacy Policy
      • Terms of Use
    Facebook X (Twitter) Instagram
    NCIJ Network NCIJ Network
    Thursday, October 22
    • Home
    • World
    • Ai
    • Business
    • Politics
    • Health
    • Crypto
    • Science
    • Technology
    • Cybersecurity
    • Defense & Security
    • Economy
    • Energy
    • Europe
    • More
      • Fact Check
      • Investigations
      • Opinion & Analysis
      • Environment
    NCIJ Network NCIJ Network
    Home»Artificial Intelligence

    Adaption Labs Introduces ‘Invent a Dataset’: Training Data Generated From a Task Description, Not a Seed Corpus

    NCIJ NETWNCIJ NETWORKBy NCIJ NETWNCIJ NETWORKSeptember 5, 2026 Artificial Intelligence No Comments4 Mins Read
    Share
    Facebook Twitter LinkedIn Pinterest Email

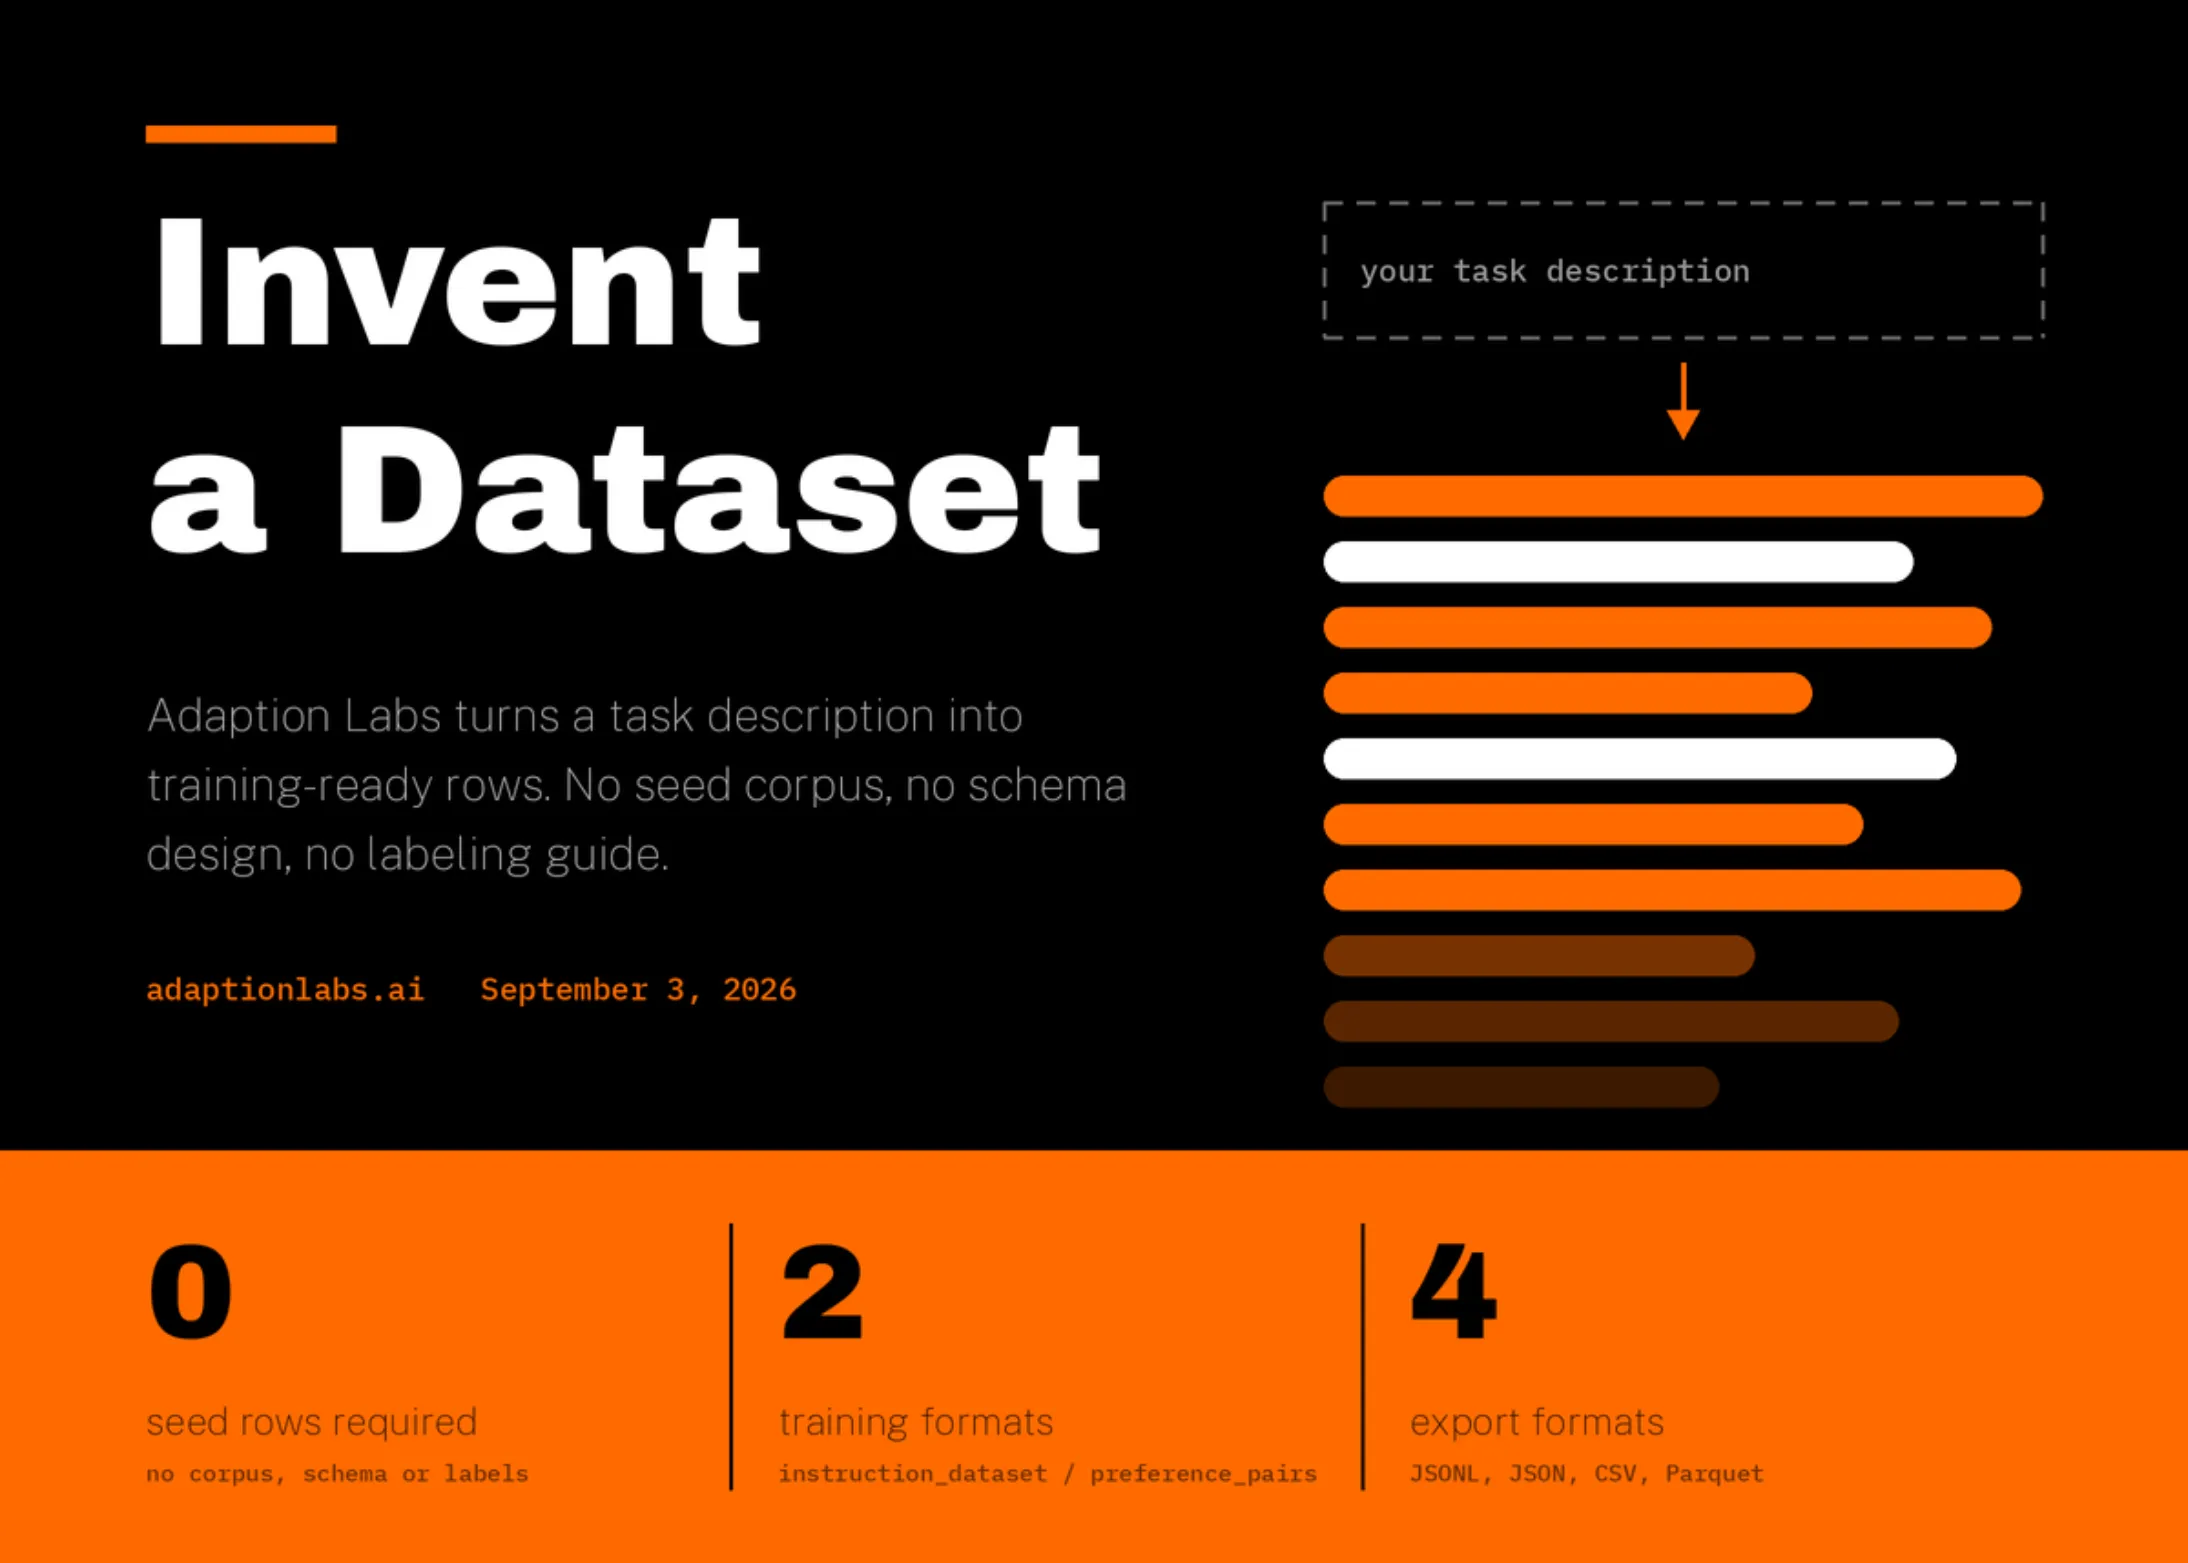
    This week, Adaption Labs released Invent a Dataset. The feature generates a structured, training-ready dataset from a description of the behavior you want a model to learn. You do not arrive with a seed corpus, a predefined schema, or a labeling guide.

    Is it deployable? Yes, with one caveat. Invent a Dataset is live now in the Adaption app and through the Python SDK and REST API. Generated rows download as JSONL, JSON, CSV, or Parquet, so the artifact is a portable file you own and can train on anywhere. Generation itself runs on Adaption’s hosted platform and consumes credits. No self-hosted generation path is documented.

    The problem being targeted

    Most dataset workflows begin with data that already exists. Teams then spend weeks labeling, filtering, and reshaping it to approximate the target task. Adaption’s argument is that this caps model quality at how closely the available data matches the intended behavior. For proprietary and specialized tasks, the relevant signal usually sits in internal systems, unstructured text, or workflow logs. It rarely converts cleanly into a focused training set.

    The research team also draws a line against existing synthetic-data tooling. Those tools automate generation after a human has already defined the schema, task distribution, and generation strategy. Invent a Dataset starts one level earlier, at the behavior itself.

    How the API works

    The mechanics are documented and concrete. A single call to datasets.invent creates the dataset and starts generation, returning immediately with status running. You then poll datasets.get until the status reads succeeded or failed, and download the rows.

    Domain codes are the primary control. You fetch current codes with datasets.invent_domains rather than hardcoding them. You then pass values such as medical, optionally narrowed by qualified subdomain codes such as medical.symptoms_diagnosis. At least one domain or subdomain is required. Multiple domains contribute to the same run. A domain passed without subdomains draws from its full scope.

    Two output formats are supported. instruction_dataset is the default and produces prompt-completion pairs for supervised fine-tuning. preference_pairs produces chosen and rejected completions for preference-based training such as DPO.

    Three parameters matter for production use. estimate=True prices the exact request and returns estimated versus available credits without creating or charging anything. prompt accepts up to 10,000 characters to steer what the rows are actually about. idempotency_key accepts up to 255 characters and makes network retries safe by returning the original dataset instead of launching a second run. Row counts are subject to a per-launch limit set by your plan.

    Language and locale expansion

    language_expansion runs in two modes. translate produces a new row variant for each target language. localize produces a variant for each country and language pair, using locale-specific wording rather than direct translation. A sample_rate between 0.01 and 1 controls what fraction of invented rows gets expanded, and credits are billed on the expanded output row count, not the original. Unsupported codes return a 400 with a sample of valid values.

    The zero-data loop

    Invent a Dataset is the first half of a loop. The dataset ID passes directly to autoscientist.create, which co-optimizes the data and the training recipe against your objective. AutoScientist launched in May 2026 and is the training-side counterpart to the Adaptive Data pillar.

    Adaption reports that AutoScientist beats training configured by its own research staff, by an average of 35%. Win rates moved from 48% to 64%. Those figures come from in-house domain-specialized evaluations across eight verticals. Dataset sizes ranged from 5,000 to 100,000 rows, on architectures offered for fine-tuning by Together AI.

    Key Takeaways

    • Invent a Dataset generates training rows from a task description, with no seed corpus, schema, or labels.
    • One datasets.invent call sets domains, row count, format, and language expansion; generation is async.
    • Output is instruction pairs or preference pairs, downloadable as JSONL, JSON, CSV, or Parquet.
    • Dataset IDs feed straight into AutoScientist, closing an intent-to-trained-model loop.

    Check out the Technical details here. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

    Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us


    Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.

    Adaption Corpus data Dataset Description Generated Introduces Invent Labs seed Task Training
    NCIJ NETWNCIJ NETWORK
    • Website

    Keep Reading

    IBM AI Releases Granite Speech 5.0 2B for Multilingual Transcription and Translation

    Perplexity and NVIDIA Researchers Introduce JOLT: a Joint Teacher-Student Reinforcement Learning Method

    A Coding Guide to Cactus Whistle: Does a 16.9 MB Speech Model Hold Up Against Whisper Base? Word Error Rate, Speed, Streaming, Timestamps, Keywords, and Speech-to-Tool Calls on a CPU

    Vercel Open-Sources durable-harness for Crash-Proof Coding Agents

    Asymptote Labs Lands $5.5 Million Seed for AI Agent Runtime Security

    Recursive Releases Flint, an Open-Weight 40B MoE Local Coding Model for Agents with 2.5B Active Params

    Add A Comment
    Leave A Reply Cancel Reply

    Editors Picks

    IBM AI Releases Granite Speech 5.0 2B for Multilingual Transcription and Translation

    October 22, 2026

    Authorities disrupt nearly 11,000 cybercrime networks in Africa

    October 22, 2026

    Fires Char New Guinea – NASA Science

    October 22, 2026

    Li Qiang and Cai Qi Are Xi Jinping’s Soldiers, Not Successors

    October 22, 2026
    Latest Posts

    Leavitt to depart the White House

    August 13, 2026

    Israeli troops force families from homes amid settler terror campaign in West Bank | West Bank

    August 13, 2026

    Video of children being taught Muslim prayers does not show a school in England – Full Fact

    August 13, 2026

    Subscribe to News

    Get the latest sports news from NewsSite about world, sports and politics.

    NCIJ Network is an independent digital news platform delivering trusted investigative journalism, European and global news, in-depth analysis, and fact-based reporting with accuracy, transparency, and integrity.

    Facebook X (Twitter) Instagram Pinterest YouTube

    IBM AI Releases Granite Speech 5.0 2B for Multilingual Transcription and Translation

    October 22, 2026

    Authorities disrupt nearly 11,000 cybercrime networks in Africa

    October 22, 2026

    Fires Char New Guinea – NASA Science

    October 22, 2026

    Subscribe to Updates

    Get the latest creative news from FooBar about art, design and business.

    Type above and press Enter to search. Press Esc to cancel.