


Perplexity has open sourced Lily, the local inference engine behind Hybrid Compute in Perplexity Computer. It is a single-process runtime: a Rust layer loads the checkpoint and drives the generation loop, an OpenAI-compatible chat-completions API streams tokens, and hand-written Metal kernels execute the model. Neither PyTorch nor MLX sits in the execution path. Lily is deliberately narrow with one model, Qwen3.6-35B-A3B, on one hardware family and that narrowness is the performance argument.
Is it deployable? Yes. A standalone demo is public in the pplx-garden repository. A Rust and Metal inference server offering greedy text generation through a minimal OpenAI-compatible HTTP API. The 4-bit checkpoint is 19.4 GB, so an Apple silicon Mac with 32 GB or more of unified memory is the realistic floor; Perplexity’s shipping Hybrid Compute product lists macOS 15+, 24 GB minimum and 32 GB for best results.
Why specialize at all?
The default Mac stack is MLX plus MLX-LM, which already ships a Qwen implementation with grouped expert work, a fused recurrent Metal kernel, and GQA-aware attention. But its operations must stay reusable across architectures. Lily gives that up and puts model structure, execution plans, and kernel selection in one runtime.
Three workload shapes
Qwen3.6-35B-A3B stores 35B parameters and activates roughly 3B per token. A router scores 256 experts and picks eight, alongside one shared expert that sees every token. It also mixes 10 full-attention layers using grouped-query attention (16 query heads, two KV heads) with 30 Gated DeltaNet layers. That yields three patterns: uneven expert groups, attention over a growing KV cache, and a fixed-size recurrence.
Prefill: keep weights packed, keep routing on the GPU
The checkpoint uses groupwise affine 4-bit quantization, every group of 64 weights sharing a bfloat16 scale and bias, about 70 GB of bfloat16 weights compressed to 19.4 GB. Metal 4 tensor operations consume bfloat16, so weights must be reconstructed first. Lily does that one tile at a time inside the grouped GEMM, holding results in threadgroup memory and accumulating in FP32, so the expanded array never reaches unified memory. In Perplexity’s ablation that fusion raised end-to-end prefill 77.4% at a 512-token prompt.
Keeping the routing histogram, prefix scan, scatter and block map inside a single GPU command buffer added 89% at 512 tokens by removing CPU synchronization inside each MoE layer. Moving from 16-row to 32-row tiles with four simdgroups added 13.2% at 2K; a register-resident Gated DeltaNet scan added 5.6%. Expert GEMMs are roughly 90% of prefill time. Long prompts run in bounded chunks so temporary activations do not compete with weights and cache for memory.
Decode: minimize bytes moved per token
Batch-1 decode has almost no weight reuse, so bandwidth sets the ceiling. One recorded step launched 795 kernels forming 555 sequential stages; Lily records real dependencies in a concurrent Metal pass so independent kernels overlap. The selected token is written straight into the next step’s GPU-resident input slot, removing a per-token CPU round trip, and four kernel chains are fused to keep intermediates in registers.
Coalesced cache reads lifted key bandwidth from 33.8 to 47.9 GB/s and value bandwidth from 42.0 to 61.8 GB/s. GQA packing, four query heads sharing one threadgroup so each KV row loads once, improved decode 23.8% at 32K. A fixed-block attention layout at 32K and above improved decode 7.7% at 32K, 27.4% at 64K, and 40.2% at 128K.
Results
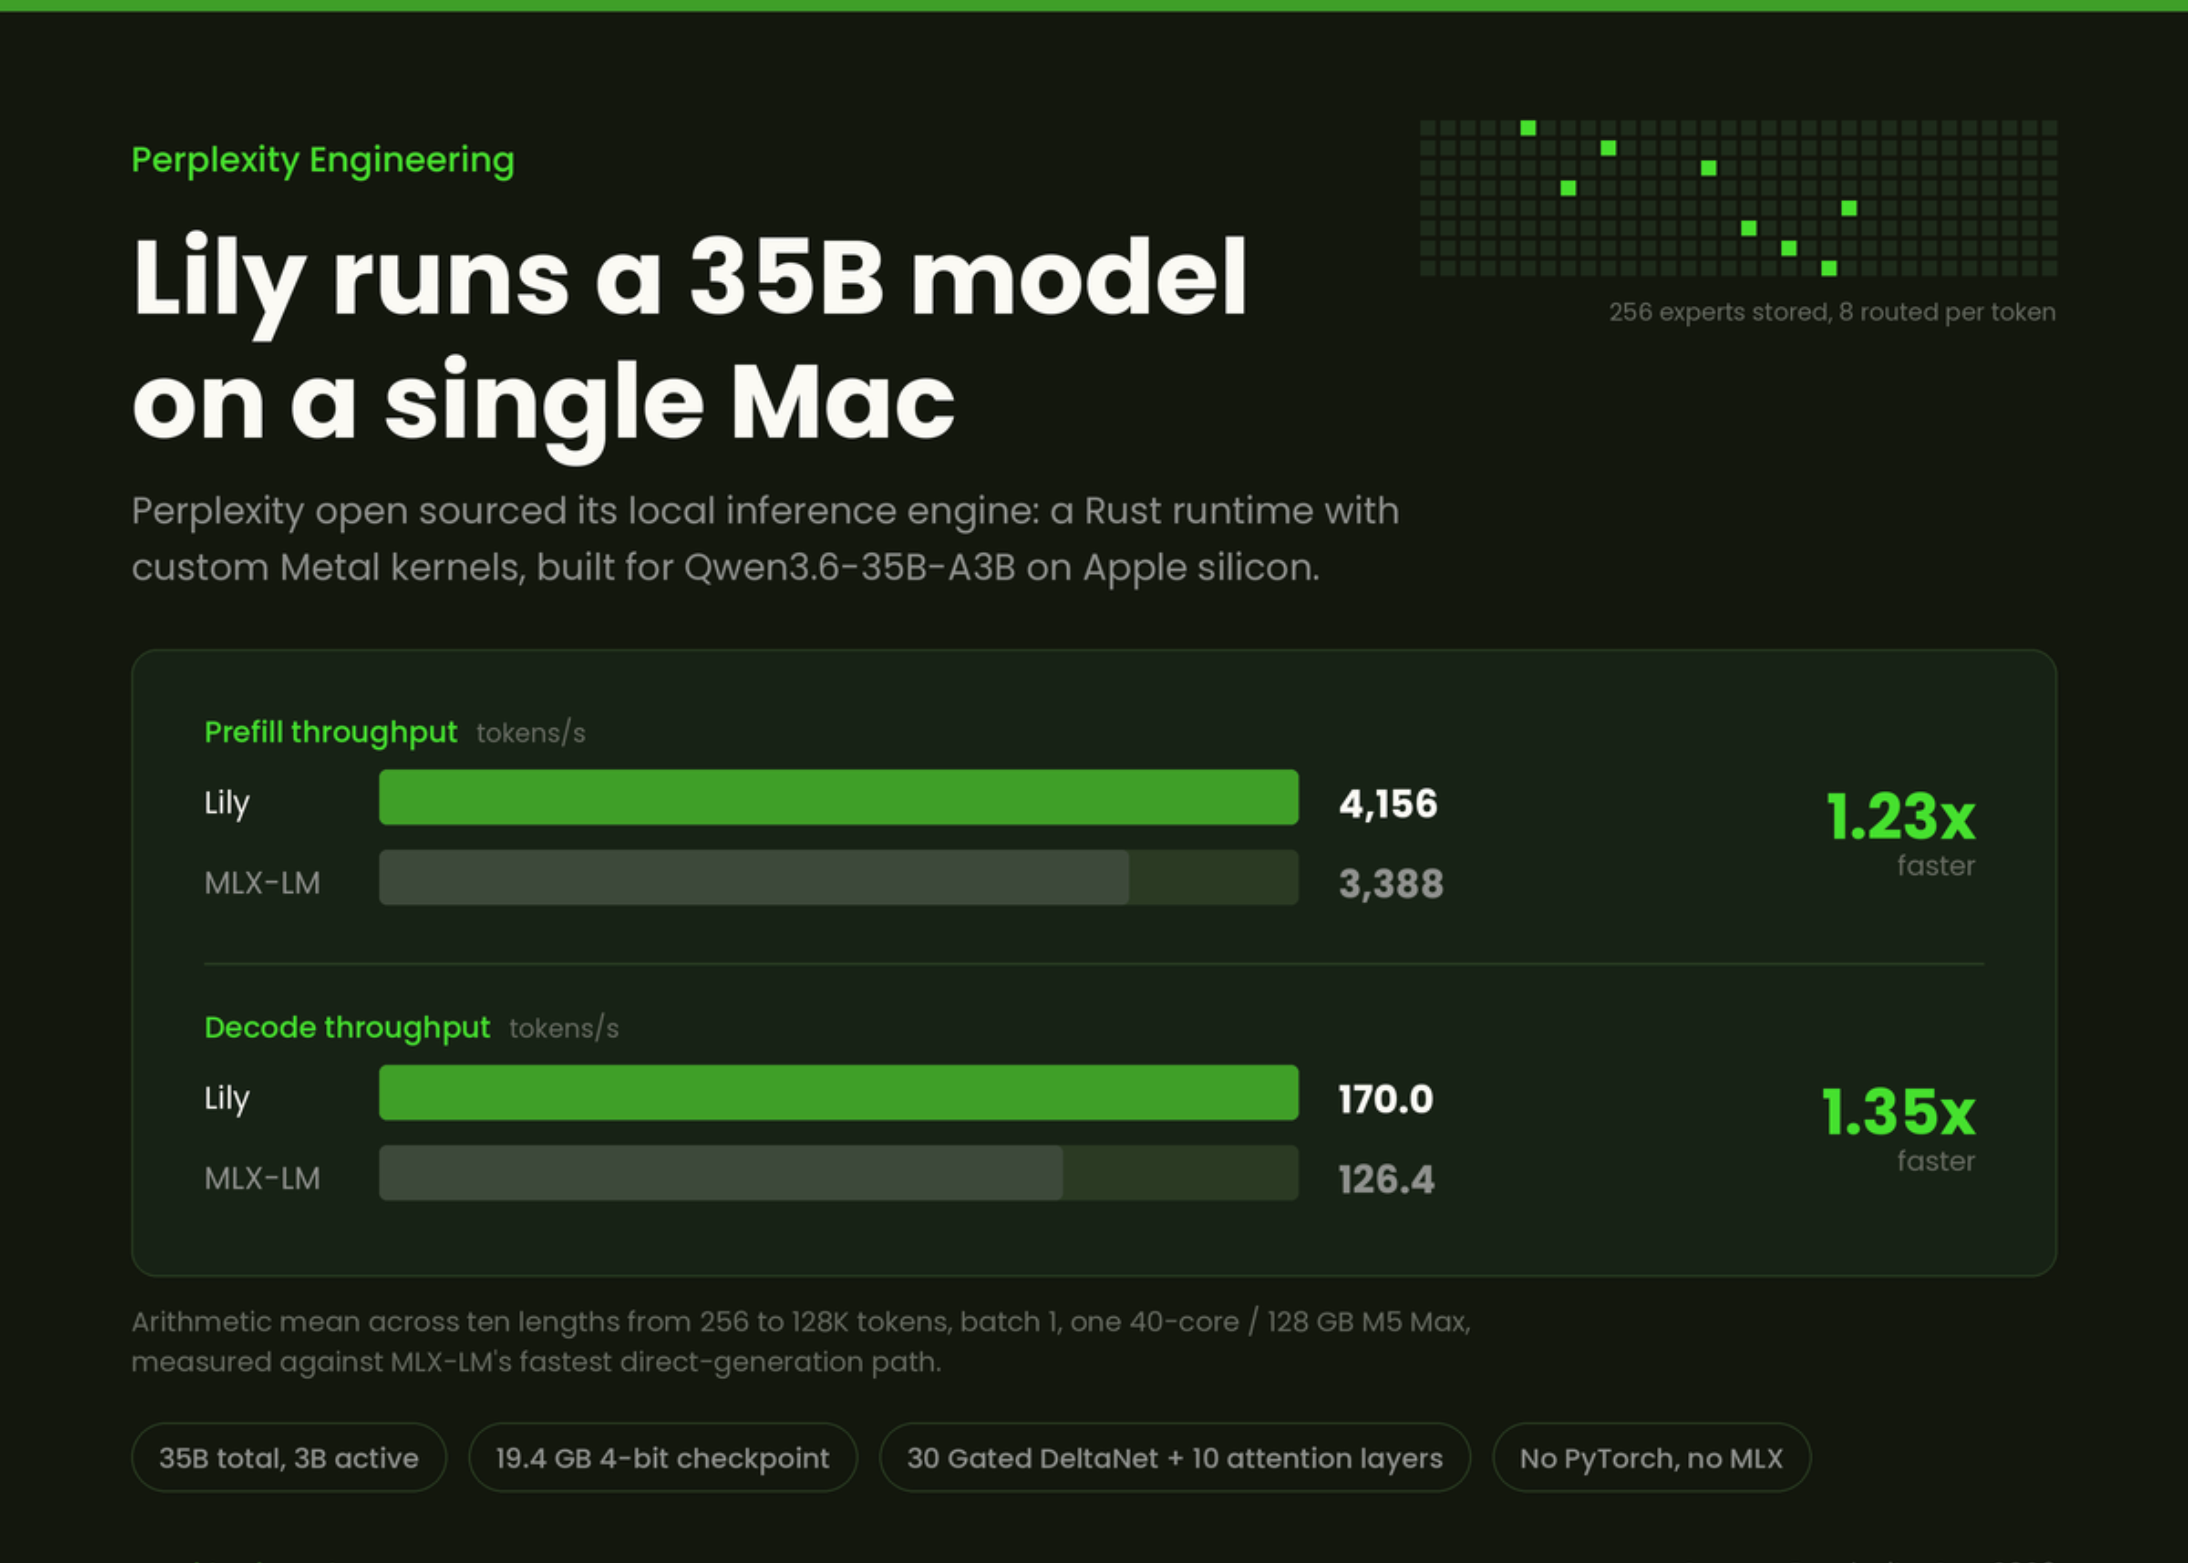
On one 40-core, 128 GB M5 Max at batch 1, loading identical 4-bit checkpoint bytes against MLX-LM’s fastest direct-generation path across ten lengths from 256 to 128K tokens, Lily averaged 4,156 prefill tokens/s versus 3,388 (1.23x) and 170.0 decode tokens/s versus 126.4 (1.35x). At a 4K prompt and 4K context it reached 5,749.9 and 186.6 tokens/s against 4,737.5 and 140.9, and was faster at every recorded point: 1.12–1.42x prefill, 1.31–1.37x decode. A teacher-forced check across 192 positions put Lily’s perplexity 0.04% higher, with the same top-ranked token 96.35% of the time.
Key Takeaways
- Lily is a Rust + Metal engine for Qwen3.6-35B-A3B on Apple silicon, with no PyTorch or MLX in the path.
- Averages 1.23x MLX-LM prefill and 1.35x decode on a 40-core, 128 GB M5 Max.
- Biggest prefill wins: GPU-resident expert routing (+89%) and dequantization fused into the grouped GEMM (+77.4%).
- Biggest decode wins: GQA packing (+23.8% at 32K) and fixed-block attention (+40.2% at 128K).
Check out the Technical details here and the GitHub Repo here. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
