

Close Menu
NCIJ Network NCIJ Network
    What's Hot

    Meet Thinking Machines Inkling 2 Mini: 26B Looped MoE Runs on a 32GB Mac

    November 21, 2026

    Scouts say they face £1m tourist tax cost for overnight trips

    November 21, 2026

    What Democrats Can Learn About Environmental Voters From the Midterms

    November 21, 2026
    Facebook X (Twitter) Instagram
    Trending
    • Meet Thinking Machines Inkling 2 Mini: 26B Looped MoE Runs on a 32GB Mac
    • Scouts say they face £1m tourist tax cost for overnight trips
    • What Democrats Can Learn About Environmental Voters From the Midterms
    • First youths arrive at Milwaukee’s new juvenile prison
    • French billionaire hunter takes fight global after California tax defeat – POLITICO
    • Could a short tail mean a new monkey species in Laos? Some scientists think so
    • Russian threats ‘less and less hybrid,’ Von der Leyen says after assassination plot in Denmark – POLITICO
    • Reform UK considers pact with Restore Britain to overcome stalling performance in polls | Reform UK
    • About
      • Our Team
      • Editorial Policy
      • Editorial Independence
      • International Support
    • Trust & Standards
      • AI Usage Policy
      • Conflict of Interest Policy
      • Corrections Policy
      • Ethics Policy
      • Fact-Checking Policy
      • Source Protection
    • Get Involved
      • Guide for Sources
      • Support Independent Journalism
    • Legal
      • Cookie Policy
      • Privacy Policy
      • Terms of Use
    Facebook X (Twitter) Instagram
    NCIJ Network NCIJ Network
    Saturday, November 21
    • Home
    • World
    • Ai
    • Business
    • Politics
    • Health
    • Crypto
    • Science
    • Technology
    • Cybersecurity
    • Defense & Security
    • Economy
    • Energy
    • Europe
    • More
      • Fact Check
      • Investigations
      • Opinion & Analysis
      • Environment
    NCIJ Network NCIJ Network
    Home»Artificial Intelligence

    Meet Thinking Machines Inkling 2 Mini: 26B Looped MoE Runs on a 32GB Mac

    NCIJ NETWNCIJ NETWORKBy NCIJ NETWNCIJ NETWORKNovember 21, 2026 Artificial Intelligence No Comments4 Mins Read
    Share
    Facebook Twitter LinkedIn Pinterest Email

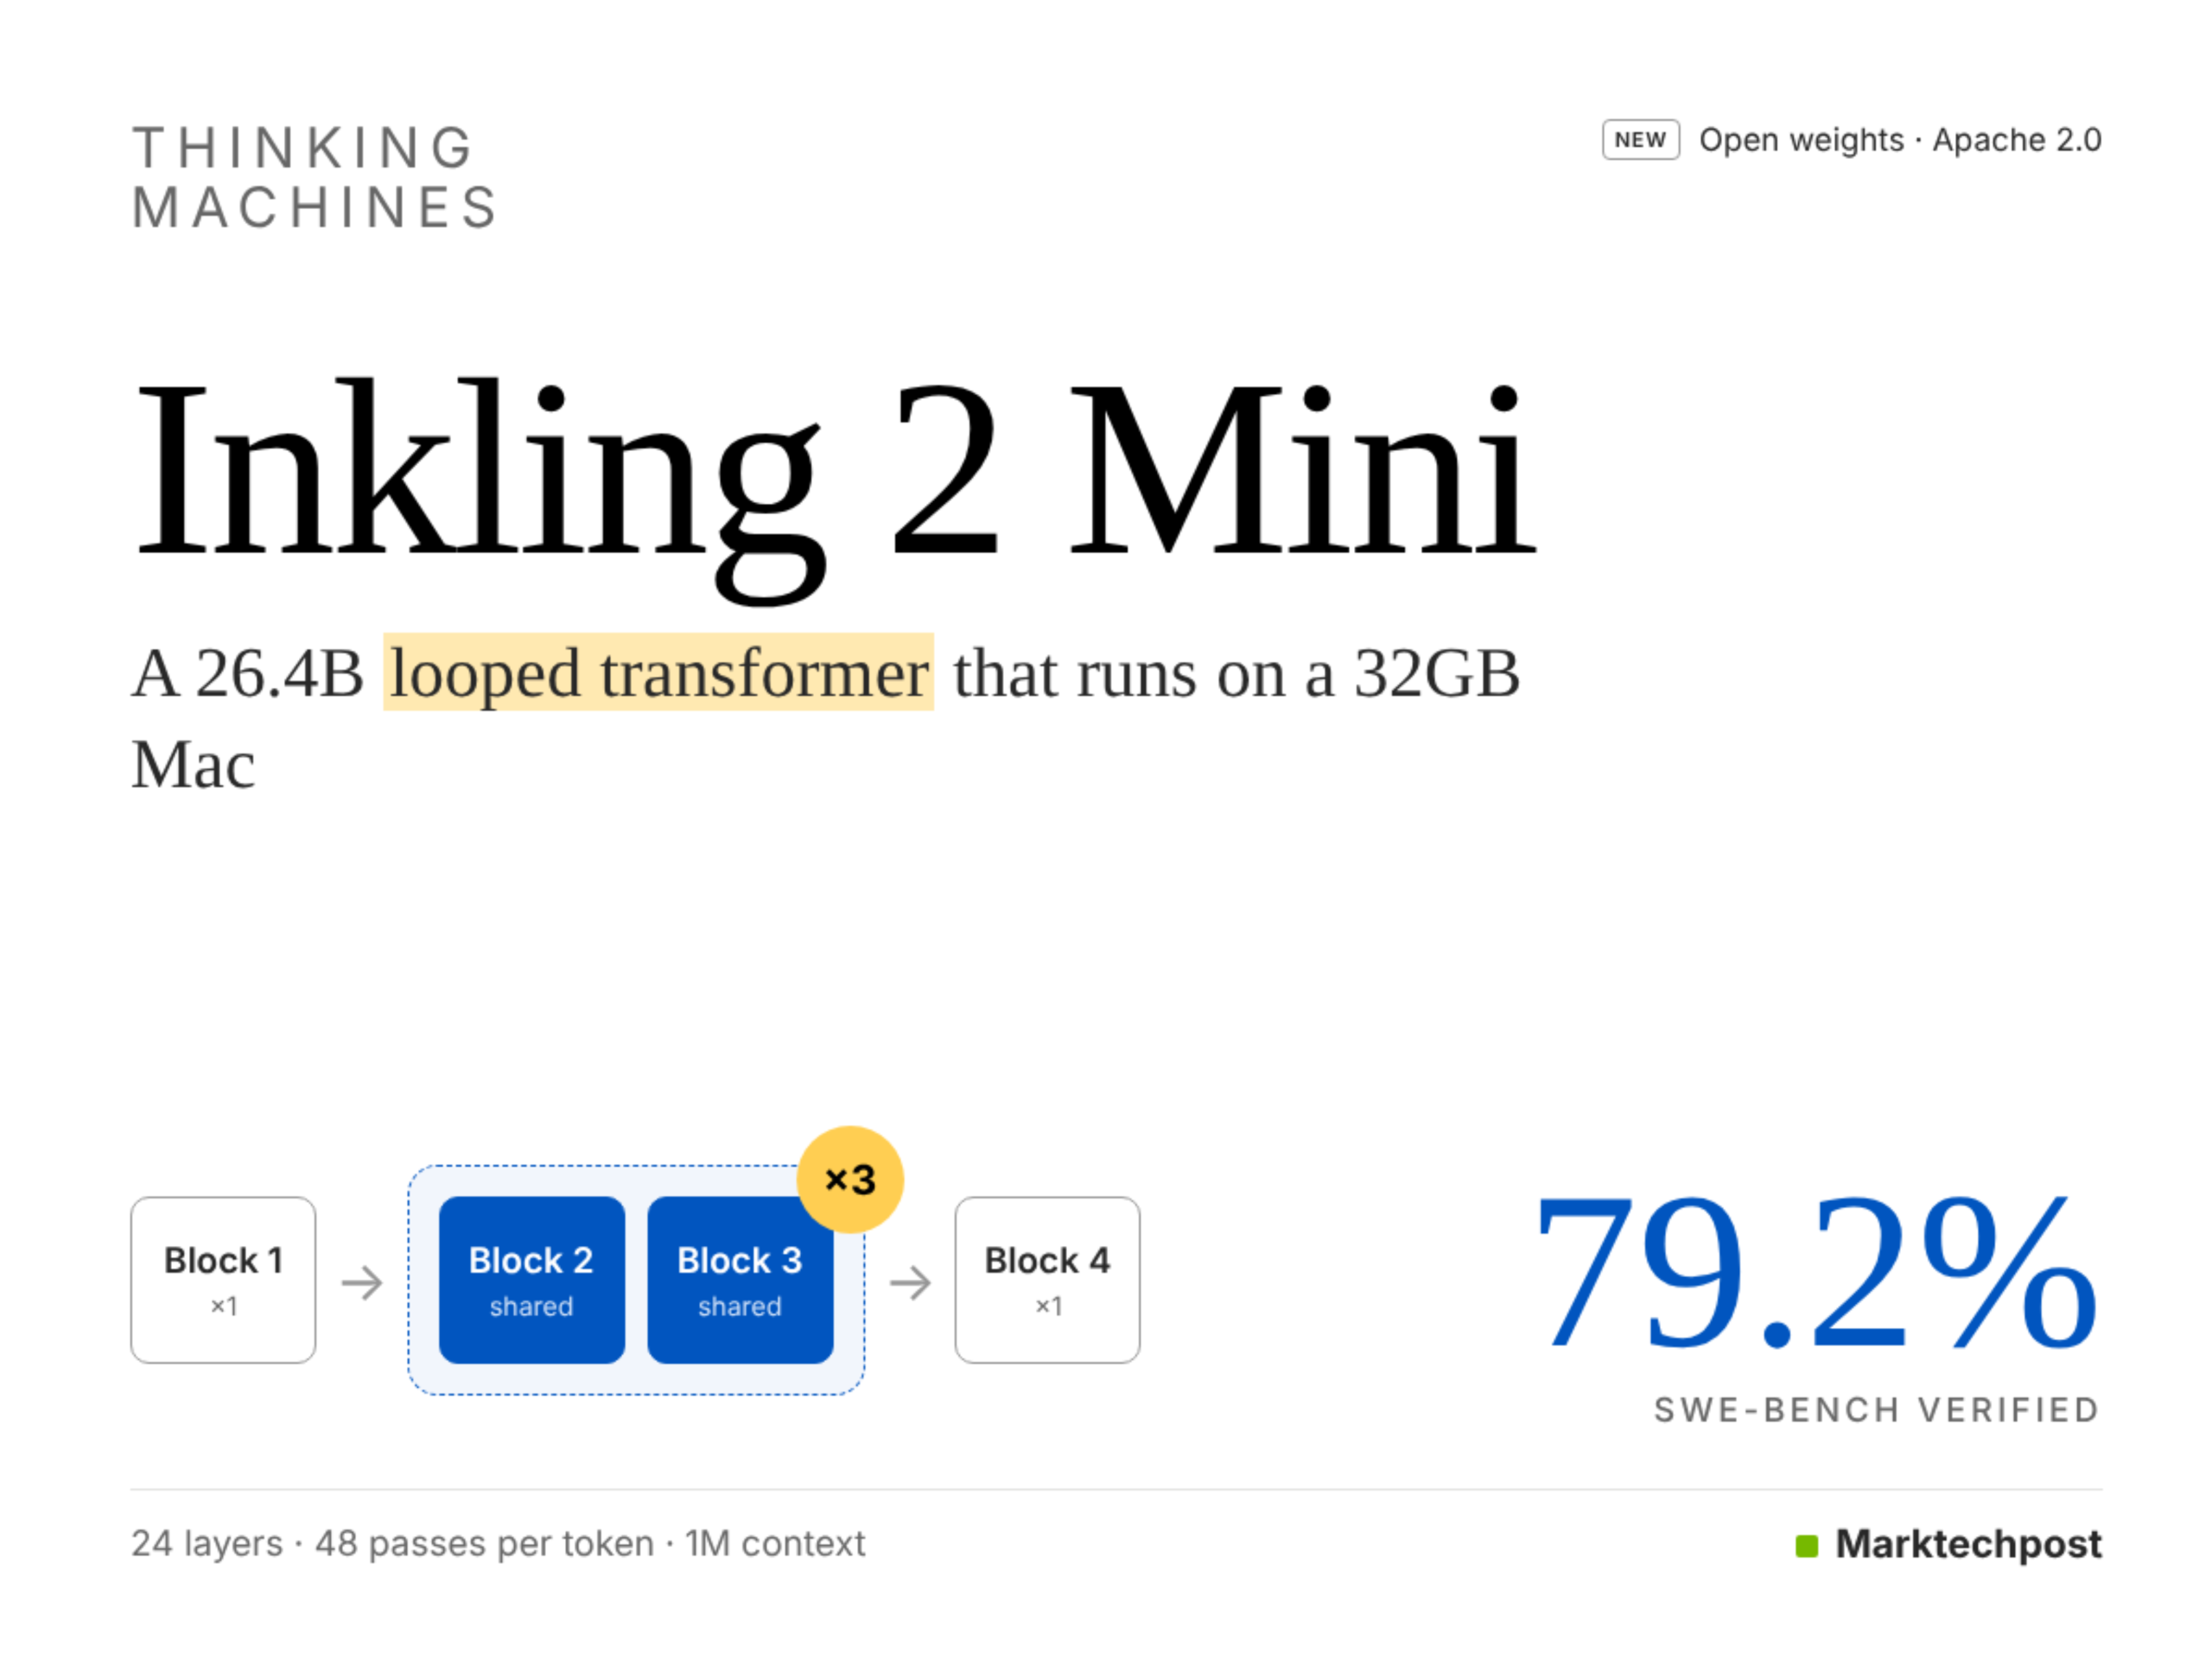
    Thinking Machines Lab has released Inkling 2 Mini, an open-weight looped transformer with 26.4B total parameters. The model reuses its middle layers 3 times per token instead of adding more weights. That keeps the checkpoint near 20GB, small enough for a 32GB Mac or 1 NVIDIA DGX Spark. For developers, Inkling 2 Mini is a local option for agentic coding, tool use and document work. It ships under Apache 2.0 on Hugging Face, with hosted inference and fine-tuning on Tinker.

    TL;DR

    • Size: 26.4B total, 3.4B active (5.4B effective per token with looping), up to 1M-token context.
    • Runs on: Apple silicon with 32GB+ memory, 1 NVIDIA DGX Spark, or GPUs with 32GB+ VRAM. GGUF builds via Unsloth and llama.cpp.
    • Performance: 20.1 on the Artificial Analysis Index, tied with Qwen3.8-27B (self-reported).
    • Best: 79.2% on SWE-bench Verified (bash only).
    • Worst: 15.2% on HLE-Diamond and 50.0% on MultiChallenge.
    • Bottom line: Best: strong agentic coding from a 20GB checkpoint. Worst: weaker knowledge recall and multi-turn instruction following.

    What is Inkling 2 Mini?

    Inkling 2 Mini is a sparse Mixture-of-Experts model from Thinking Machines that loops its middle layers. It accepts text and images and returns text only.

    It follows Inkling 2 Small, a 594B-parameter model released on November 5.

    How does the looped transformer work?

    The model stores 24 layers, grouped into 4 blocks of 6. The first and last blocks run once. The 2 middle blocks run 3 times with shared weights. That gives 48 layer applications per token from 24 layers of weights.

    Each pass after the first receives a “message” from the previous pass. Thinking Machines carries it with Attention Residuals and a learned gate. Feed-forward layers use 128 experts, with 8 routed per token.

    Looping the middle layers gave a 1.51x to 1.91x compute-equivalent gain. Looping the last layers gave only 1.24x to 1.36x. The middle-loop variant won 27 of 28 evaluations.

    Looping costs training compute but saves inference. An unlooped baseline used 7.5% less training compute. It needed 140% more inference compute to match the looped model’s loss on 512k-token agentic traces.

    How was Inkling 2 Mini trained?

    Training began with 384 experts per layer, with 8 active per token. At midtraining, the team pruned two-thirds of them and kept the 128 most-used experts. A 1T-token distillation run from a larger internal Inkling model then healed the pruned model. Post-training used SFT, then RL over 2.2T tokens and 2,000 steps, plus on-policy distillation.

    Expert layers are trained and deployed in NVFP4. The last 4 layers use MXFP8. Thinking Machines says this removes quantization conversion loss. A research variant, TML-d24-varloop-research, trains with 1 to 5 passes.

    How does Inkling 2 Mini perform on benchmarks?

    All Inkling scores below are self-reported by Thinking Machines. Coding is the strongest area. Inkling 2 Mini scores 79.2% on SWE-bench Verified (bash only) and 77.9% on SWE-bench Pro v2 (Hard). It reaches 48.2% on DeepSWE v1.1, where Qwen’s own card lists Qwen3.8-27B at 42.2%. On Terminal Bench v2.1 it scores 71.6%, behind Qwen3.8-27B at 73.0%.

    Agentic search also holds up: 79.0% on BrowseComp with compaction and 82.7% on MCP Atlas. For documents and vision, it posts 92.8% on OmniDocBench v1.6 and 74.9% on MMMU Pro. On reasoning, it scores 86.6% on GPQA Diamond and 49.3% on ARC-AGI-2.

    Efficiency is the headline claim. On Stanford’s Intelligence per Watt metric, Thinking Machines reports 0.703 on a DGX Spark. It lists Qwen3.6-35B-A3B at 0.430 and Gemma-4-26B-A4B at 0.159.

    26B 32GB Inkling Looped Mac machines Meet mini MoE Runs Thinking
    NCIJ NETWNCIJ NETWORK
    • Website

    Keep Reading

    Baseten Releases Bison-1 and Groundhog-1, Topping Decision Model Index

    RadixArk Ships DaisyRose-27B, a 27B Agentic Coding Model Trained With Reinforcement Learning Only

    NVIDIA AI Releases Nemotron-Labs-Sigma, a Continuous Diffusion Language Model with 14 checkpoints at 3B/8B

    Perplexity Launches Orchestrator API for Failover and Model Routing

    Meta FAIR Self-Improving Memory Hits 56.0 on Continual Learning Bench

    13 Best Agent Gateways in 2026 for MCP, A2A and LLM Traffic: Kong, Bifrost, AgentCore, Arcade

    Add A Comment
    Leave A Reply Cancel Reply

    Editors Picks

    Meet Thinking Machines Inkling 2 Mini: 26B Looped MoE Runs on a 32GB Mac

    November 21, 2026

    Scouts say they face £1m tourist tax cost for overnight trips

    November 21, 2026

    What Democrats Can Learn About Environmental Voters From the Midterms

    November 21, 2026

    First youths arrive at Milwaukee’s new juvenile prison

    November 21, 2026
    Latest Posts

    Unpacking claim USS Doris Miller will be renamed after Trump instead of Black WWII hero

    August 21, 2026

    Iran Vows ‘Devastating’ Retaliation Against New U.S. Sanctions Threats

    August 21, 2026

    Bomb Fishing Is Reducing Coral Reefs to ‘Rubble’

    August 21, 2026

    Subscribe to News

    Get the latest sports news from NewsSite about world, sports and politics.

    NCIJ Network is an independent digital news platform delivering trusted investigative journalism, European and global news, in-depth analysis, and fact-based reporting with accuracy, transparency, and integrity.

    Facebook X (Twitter) Instagram Pinterest YouTube

    Meet Thinking Machines Inkling 2 Mini: 26B Looped MoE Runs on a 32GB Mac

    November 21, 2026

    Scouts say they face £1m tourist tax cost for overnight trips

    November 21, 2026

    What Democrats Can Learn About Environmental Voters From the Midterms

    November 21, 2026

    Subscribe to Updates

    Get the latest creative news from FooBar about art, design and business.

    Type above and press Enter to search. Press Esc to cancel.