


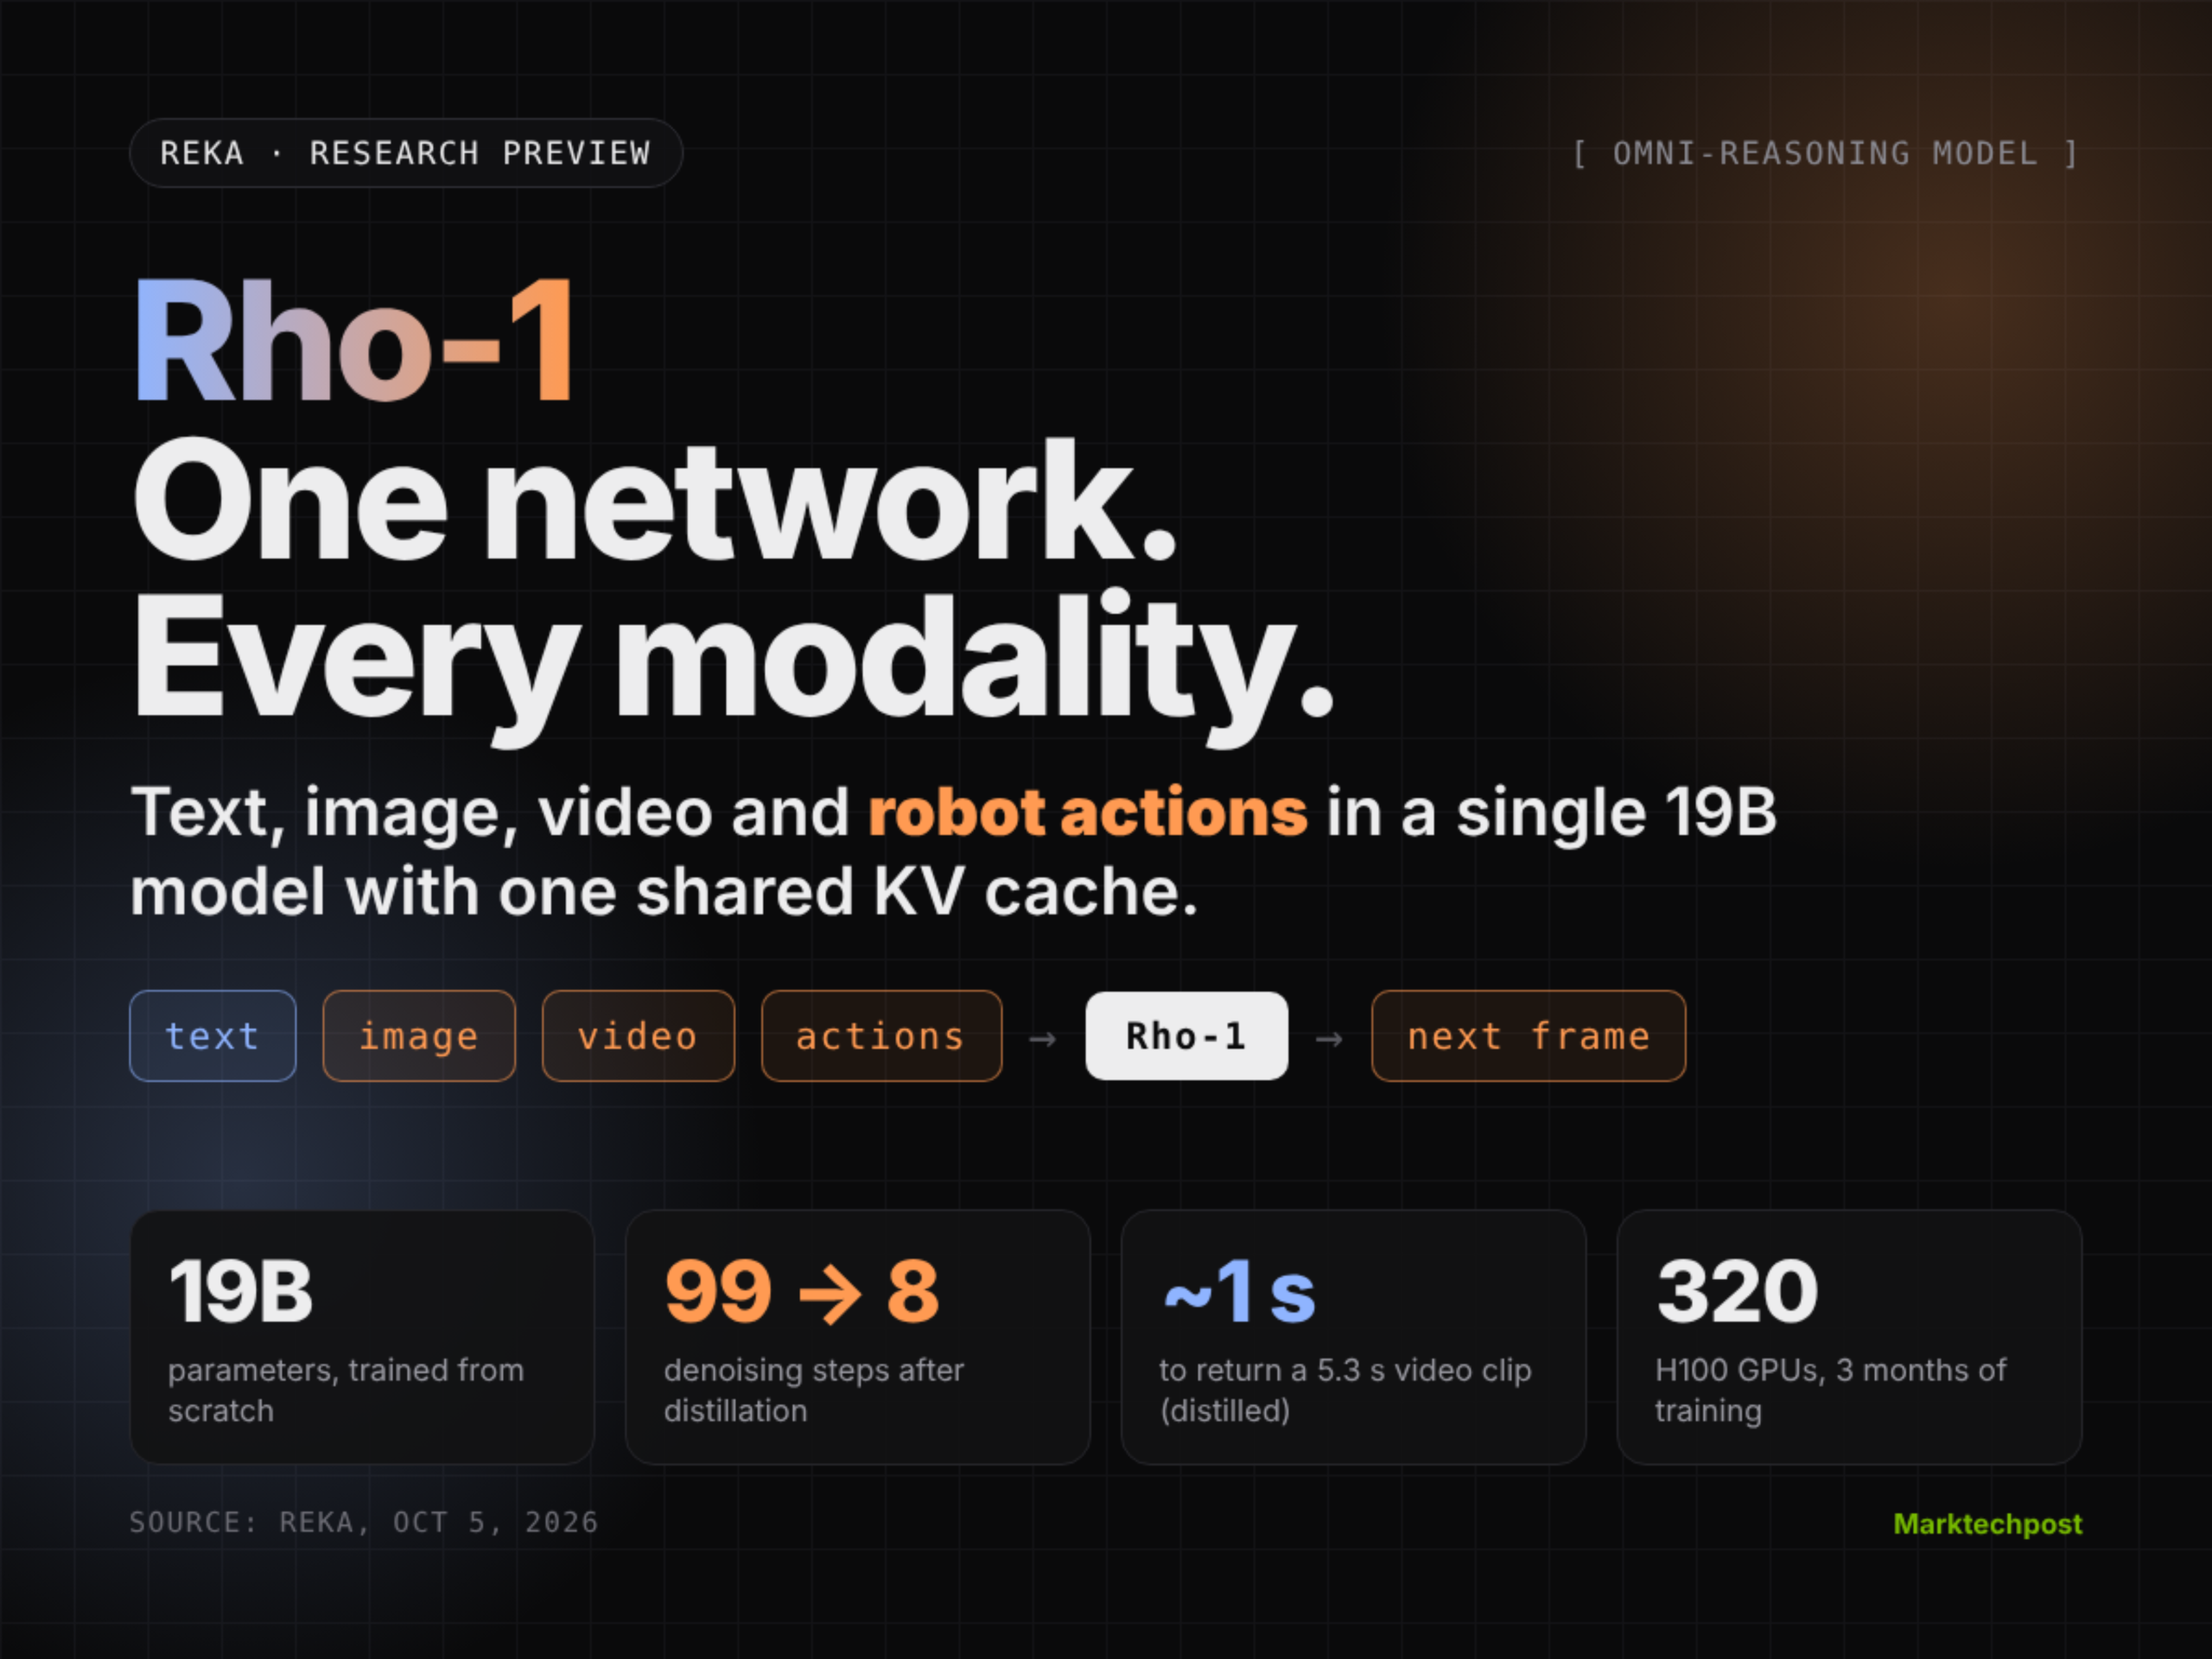
Reka has released a research preview of Rho-1, a 19B omni-reasoning model trained from scratch. A single neural network understands and generates text, images and video, reasons over them, and outputs robot actions. Reka frames it as a direct replacement for agentic pipelines that pass work between modality-specific models.
What Rho-1 Changes
Most multimodal systems today are pipelines. A central model plans, then hands jobs to specialists for images, video or detection. Each handoff adds latency, and each specialist sees only a narrow request.
Rho-1 removes those handoffs. Text, vision and robotic actions become tokens inside one context window. According to Reka’s research, one unedited session shows the full loop. The model draws a lighthouse, boxes it, animates it, edits the video into a snowstorm, and explains the difference. That all happens in 5 turns, with no tool call and no second model.
Architecture: Two Streams, One KV Cache
Every input and output uses one of two native formats:
- Discrete tokens carry text, symbolic reasoning and high-level commands.
- Continuous tokens carry image latents, video frames, robot actions and proprioception.
Each transformer block holds two expert weight streams. The understanding stream handles language and visual parsing. The generation stream denoises latents into images and video. Both streams share attention and operate over the same KV cache.
When a reply needs pixels, the understanding stream emits a discrete handoff token. The generation stream then renders from the full accumulated state. Training combines next-token prediction for discrete sequences with flow matching for continuous outputs.
This design has practical effects. Bounding boxes come out as coordinate tokens, not from a separate detector. A video’s first frame reuses the in-context image representation instead of a re-encoded copy.
‘;B.appendChild(r)});
var rows=[].slice.call(B.querySelectorAll(‘.row’)).reverse();
var timers=[];function clr(){timers.forEach(clearTimeout);timers=[]}
function T(f,ms){timers.push(setTimeout(f,ms))}
function sweep(kind,start){rows.forEach(function(r,i){var l=r.querySelector(‘.lane.’+kind);T(function(){l.classList.add(‘hot’)},start+i*110);T(function(){l.classList.remove(‘hot’)},start+i*110+420)})}
var KV=document.getElementById(‘kv’),CAP=document.getElementById(‘cap’),LOOP=document.getElementById(‘loop’);
function chip(txt,c,ms){T(function(){var s=document.createElement(‘span’);s.className=”chip mono “+c;s.textContent=txt;KV.appendChild(s);sz()},ms)}
function denoise(ms,label){T(function(){LOOP.innerHTML=label+’ ‘+’‘.repeat(8)+’ 8 passes (distilled)‘;var p=LOOP.querySelectorAll(‘.pip’);p.forEach(function(x,i){T(function(){x.classList.add(‘on’);rows.forEach(function(r){var l=r.querySelector(‘.lane.g’);l.classList.add(‘hot’);T(function(){l.classList.remove(‘hot’)},160)})},i*190)})},ms)}
var turns=[
{u:'”Draw a lighthouse on a headland”‘,cap:’Draw. The understanding stream reasons and writes a shot plan, then emits a handoff token. The generation stream denoises image:0 from the full accumulated state.’,gen:’image:0′,plan:true},
{u:'”Put a box around the lighthouse”‘,cap:’Box. No detection model. The box is emitted as coordinate tokens attending to image:0, which is already in context because Rho-1 generated it.’,txt:’box tokens’},
{u:'”Animate: drone flies toward it”‘,cap:’Animate. The first frame is not a re-encoded image. It is the original representation held in context, so lighting and geometry carry through.’,gen:’video:0′,plan:true},
{u:'”Edit: heavy snowstorm”‘,cap:’Edit. video:1 keeps the scene, lighthouse and camera move from video:0, with the weather changed.’,gen:’video:1′,plan:true},
{u:'”What changed between the videos?”‘,cap:’Ask. No post-hoc captioning of exported frames. Rho-1 reads the latent state that produced the change and answers in text.’,txt:’answer text’}];
var ti=0;
function run(k,base){var t=turns[k];base=base||0;
T(function(){CAP.innerHTML=t.cap;LOOP.innerHTML=”;sz()},base);
chip(‘text: user ‘+t.u,’u’,base+100);sweep(‘u’,base+150);
if(t.plan){chip(‘thinking + shot plan’,’u’,base+800);chip(‘<|content_media|> handoff’,’h’,base+1200);denoise(base+1400,’Generation stream’);chip(t.gen,’g’,base+3100);return base+3500}
chip(t.txt,’u’,base+900);sweep(‘u’,base+700);return base+1500}
function reset(){clr();KV.innerHTML=”;LOOP.innerHTML=”;ti=0;CAP.innerHTML=’Press Play session to replay Reka’s 5-turn demo. Every turn reads from and writes to the same KV cache. No tool call, no second model.’;R.querySelectorAll(‘#turns .b’).forEach(function(b){b.classList.remove(‘on’)});sz()}
document.getElementById(‘reset’).onclick=reset;
document.getElementById(‘playall’).onclick=function(){reset();var t0=200;turns.forEach(function(_,k){(function(k,t0){T(function(){mark(k)},t0)})(k,t0);t0=run(k,t0)+400})};
function mark(k){R.querySelectorAll(‘#turns [data-k]’).forEach(function(b){b.classList.toggle(‘on’,+b.dataset.k===k)})}
R.querySelectorAll(‘#turns [data-k]’).forEach(function(b){b.onclick=function(){clr();mark(+b.dataset.k);run(+b.dataset.k,0)}});
/* race */
var P=[[‘route’,’#5a5a63′,1.6],[‘expand prompt’,’#6d6d76′,2.6],[‘queue’,’#5a5a63′,2.2],[‘generate’,’#ff9a52′,5.8],[‘return’,’#6d6d76′,1.6]];
var Q=[[‘plan’,’#8fb4ff’,1.6],[‘generate’,’#ff9a52′,5.4]];
var MAX=13.8;
function build(id,arr){var tr=document.getElementById(id);tr.innerHTML=”;var x=0;arr.forEach(function(s){var d=document.createElement(‘div’);d.className=”seg mono”;d.style.left=(x/MAX*100)+’%’;d.style.background=s[1];d.dataset.w=(s[2]/MAX*100);d.dataset.d=s[2];d.textContent=s[0];tr.appendChild(d);x+=s[2]})}
build(‘tr1’,P);build(‘tr2’,Q);
var raceT=[];
document.getElementById(‘race’).onclick=function(){raceT.forEach(clearTimeout);raceT=[];build(‘tr1’,P);build(‘tr2’,Q);
var SC=380;
[‘tr1′,’tr2’].forEach(function(id,j){var acc=0,segs=document.getElementById(id).querySelectorAll(‘.seg’),tot=j?7.0:13.8,lab=document.getElementById(j?’t2′:’t1′);
segs.forEach(function(s){(function(s,acc){raceT.push(setTimeout(function(){s.style.transitionDuration=(s.dataset.d*SC)+’ms’;s.style.width=s.dataset.w+’%’},acc*SC+30))})(s,acc);acc+=+s.dataset.d});
var st=Date.now();(function tick(){var e=(Date.now()-st)/SC;if(e>=tot){lab.textContent=tot.toFixed(1)+’ s’;return}lab.textContent=e.toFixed(1)+’ s’;raceT.push(setTimeout(tick,40))})()})};
/* steps */
var S=document.getElementById(‘steps’),SCAP=document.getElementById(‘scap’),stT=[];
function steps(n){stT.forEach(clearTimeout);stT=[];S.innerHTML=’‘.repeat(n);var e=S.querySelectorAll(‘.st’),dur=2400;e.forEach(function(x,i){stT.push(setTimeout(function(){x.classList.add(‘on’)},i*(dur/n)))});
SCAP.textContent=n===99?’Base model: 99 denoising passes per clip. Rho-1 base generates video at 0.79x real-time (median).’:’Distilled model: 8 passes. Reka reports minimal quality loss and a 5.3 s clip returned in about a second.’;sz()}
document.getElementById(‘s99’).onclick=function(){this.classList.add(‘on’);document.getElementById(‘s8’).classList.remove(‘on’);steps(99)};
document.getElementById(‘s8’).onclick=function(){this.classList.add(‘on’);document.getElementById(‘s99’).classList.remove(‘on’);steps(8)};
steps(99);
/* symmetry */
var CH=[[‘text’,’d’,’Text, reasoning and commands are discrete tokens trained with next-token prediction.’],[‘image’,’c’,’Image latents are continuous tokens, generated with flow matching. No lossy quantization into discrete codes.’],[‘video’,’c’,’Video frames are continuous tokens. Predicting the next frame is the same operation as predicting the next word.’],[‘actions’,’c’,’Robot actions are continuous tokens in the same attention space. In a LIBERO episode Rho-1 emits 7 action channels.’],[‘proprioception’,’c’,’Proprioception is a continuous channel, so the policy can mentally simulate the next few seconds before acting.’]];
var CI=document.getElementById(‘cin’),CO=document.getElementById(‘cout’),CORE=document.getElementById(‘core’),PL=document.getElementById(‘pl’),YC=document.getElementById(‘ycap’);
CH.forEach(function(c,i){var a=document.createElement(‘button’);a.className=”ch mono “+c[1];a.textContent=c[0]+’ in’;a.onclick=function(){CI.querySelectorAll(‘.ch’).forEach(function(x){x.classList.remove(‘on’)});CO.querySelectorAll(‘.ch’).forEach(function(x){x.classList.remove(‘on’)});a.classList.add(‘on’);PL.style.background=c[1]===’d’?’#8fb4ff’:’#ff9a52′;CORE.classList.remove(‘go’);void CORE.offsetWidth;CORE.classList.add(‘go’);setTimeout(function(){CO.children[i].classList.add(‘on’)},500);YC.textContent=c[2];sz()};CI.appendChild(a);
var o=document.createElement(‘div’);o.className=”ch mono “+c[1];o.textContent=”future “+c[0];CO.appendChild(o)});
sz();
})();
“>
Speed: Base vs Distilled
The base model generates video at 0.79x real-time (median), with a watchable stream starting in roughly 6 seconds. Reka team measured 7.0 seconds to a first clip, against an illustrative 13.8 seconds for a multi-agent pipeline.
A distilled variant cuts denoising from 99 steps to 8, with minimal quality loss reported. It returned a 5.3-second clip in about a second. In Reka’s internal tests, it matched the fastest dedicated image models. It was also the quickest model tested to the first text token. These are vendor-run tests, not independent benchmarks.
World Model and Robotics
Rho-1 streams continuously, clip after clip. New instructions enter through the understanding stream and update state mid-rollout. Reka demonstrates one opening forked into ‘bank left’ and ‘bank right’ continuations.
For robotics, actions and future frames decode from the same latent state. A LIBERO simulation episode shows Rho-1 emitting 7 action channels. To scale past scarce teleoperation logs, Reka pairs Rho-1 with its Inverse Dynamics Model, which infers control signals from raw video.
How Rho-1 Compares
Data verified on October 5, 2026 from official sources.
| Feature | Reka Rho-1 | ByteDance BAGEL | BAAI Emu3.5 | Google Genie 3 |
|---|---|---|---|---|
| Developer | Reka | ByteDance Seed | BAAI | Google DeepMind |
| Parameters | 19B | 14B total, 7B active (MoT) | 34B | Not disclosed |
| Inputs | Text, image, video, actions, proprioception | Text, image | Interleaved text and image | Text prompt, navigation inputs |
| Outputs | Text, image, video, actions, proprioception | Text, image | Interleaved text and image | Interactive video world |
| Native video generation | Yes, capped at 672×384 | No | No (image frames, not native clips) | Yes, 720p at 24 fps |
| Real-time steering | Yes, continuous rollouts | No | No | Yes, promptable world events |
| Robot actions | Native continuous action tokens | No | Embodied manipulation demos | Takes navigation actions, does not emit them |
| Open weights | No | Yes, Apache 2.0 | Yes, Apache 2.0 | No |
| Access today | Research preview via [email protected] | Hugging Face, GitHub | Hugging Face, emu.world app | Project Genie for Google AI Ultra subscribers |
| Source/Resources | Reka blog | GitHub | Hugging Face | DeepMind blog |
Genie 3 access per Project Genie; Emu3.5 parameter count per its Hugging Face model card.
Key Takeaways
- Rho-1 is a 19B model that reads and writes text, image, video and robot actions.
- Two expert streams share attention and one KV cache in every block.
- Distillation cuts denoising from 99 to 8 steps, about 1 second per 5.3 s clip.
- Trained on 320 H100s for 3 months; video is capped at 672×384.
- Research preview only: no public weights, API or pricing yet.
Check out the Technical details and the announcement on X. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us

Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.
