


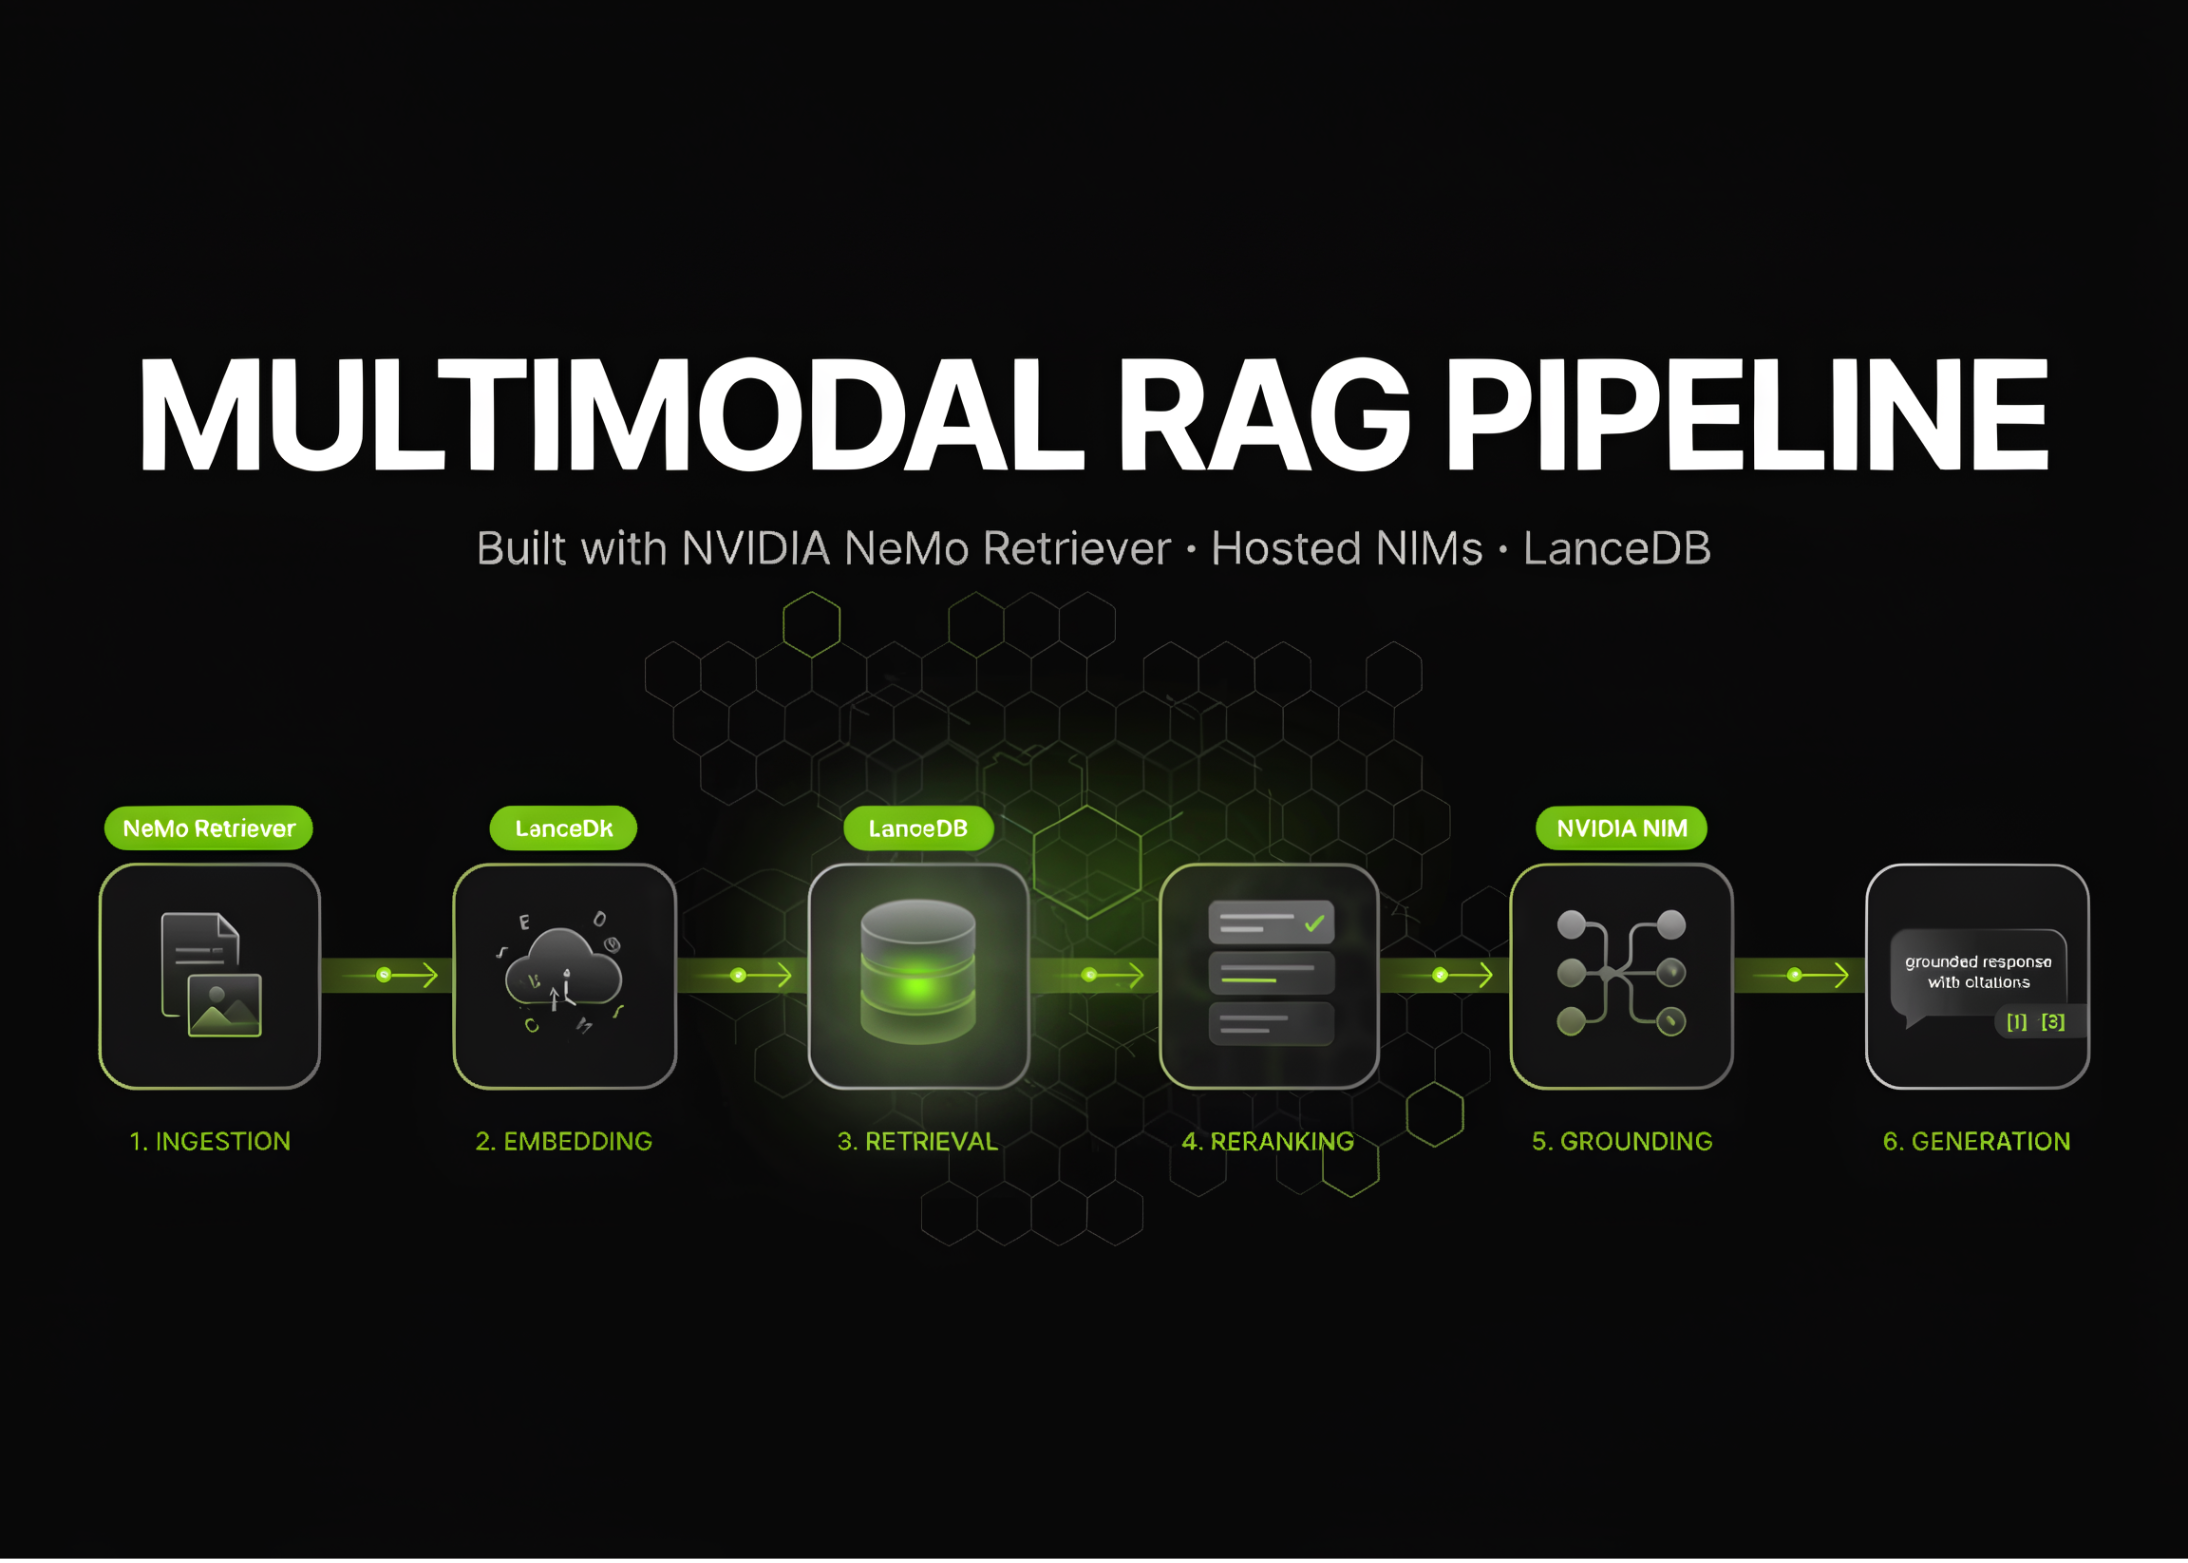
In this tutorial, we build an advanced multimodal retrieval-augmented generation pipeline with NVIDIA NeMo Retriever. We begin by configuring a Python 3.12 environment, installing the required packages, and performing offline PDF text extraction without relying on a GPU or external API key. We then extend the workflow with hosted NVIDIA NIM endpoints to detect page elements, extract tables, charts, and infographics, generate dense vector embeddings, and store the processed content in LanceDB. Finally, we implement dense retrieval, vision-language reranking, metadata-filtered search, grounded response generation with inline citations, and a lightweight recall-at-k evaluation to validate retrieval quality across multimodal document content.
import sys, os, subprocess, textwrap, json, time, warnings
warnings.filterwarnings("ignore")
assert sys.version_info[:2] == (3, 12), (
   f"nemo-retriever requires Python 3.12.x (found {sys.version.split()[0]}). "
   "Colab's default runtime is 3.12; if you changed it, switch back."
)
def sh(cmd):
   print(f"$ {cmd}")
   subprocess.run(cmd, shell=True, check=False)
try:
   import nemo_retriever
   print("nemo-retriever already installed")
except ImportError:
   sh("pip install -q --ignore-installed PyJWT nemo-retriever openai")
import nemo_retriever
print("nemo-retriever version:", nemo_retriever.__version__)
from nemo_retriever import create_ingestor
try:
   from nemo_retriever.io import to_markdown, to_markdown_by_page
except ImportError:
   from nemo_retriever.common.io import to_markdown, to_markdown_by_page
try:
   from nemo_retriever.retriever import Retriever
except ImportError:
   from nemo_retriever.graph.retriever import Retriever
import pandas as pd
pd.set_option("display.max_colwidth", 160)
DOC = "multimodal_test.pdf"
if not os.path.exists(DOC):
   sh(f"curl -sL -o {DOC} "
      "https://raw.githubusercontent.com/NVIDIA/NeMo-Retriever/main/data/multimodal_test.pdf")
print("document:", DOC, os.path.getsize(DOC), "bytes")
DOCS = [DOC]
print("n=== STAGE 1: offline text extraction (no API key) ===")
offline = (
   create_ingestor(run_mode="inprocess", allow_no_gpu=True)
   .files(DOCS)
   .extract(
       extract_text=True,
       extract_tables=False, extract_charts=False,
       extract_images=False, extract_infographics=False,
       use_page_elements=False,
       extract_page_as_image=False,
       method="pdfium",
   )
)
df_offline = offline.ingest()
print("rows:", df_offline.shape, "ncolumns:", list(df_offline.columns))
print("npage 1 text preview:n", df_offline.iloc[0]["text"][:400])
We configure the Python 3.12 environment, install NVIDIA NeMo Retriever, and import the required ingestion and retrieval components. We download the sample multimodal PDF and define it as the input document for the pipeline. We then perform CPU-based offline text extraction with PDFium and inspect the extracted rows, columns, and page content.
from getpass import getpass
if not os.environ.get("NVIDIA_API_KEY"):
   try:
       from google.colab import userdata
       os.environ["NVIDIA_API_KEY"] = userdata.get("NVIDIA_API_KEY")
   except Exception:
       os.environ["NVIDIA_API_KEY"] = getpass("NVIDIA_API_KEY (nvapi-...): ").strip()
API_KEY = os.environ.get("NVIDIA_API_KEY", "").strip()
HAVE_KEY = API_KEY.startswith("nvapi-")
print("API key present:", HAVE_KEY)
PAGE_ELEMENTS_URL   = "https://ai.api.nvidia.com/v1/cv/nvidia/nemotron-page-elements-v3"
OCR_URL             = "https://ai.api.nvidia.com/v1/cv/nvidia/nemotron-ocr-v1"
TABLE_STRUCT_URL    = "https://ai.api.nvidia.com/v1/cv/nvidia/nemotron-table-structure-v1"
GRAPHIC_ELEM_URL    = "https://ai.api.nvidia.com/v1/cv/nvidia/nemotron-graphic-elements-v1"
EMBED_URL           = "https://integrate.api.nvidia.com/v1/embeddings"
RERANK_URL          = "https://ai.api.nvidia.com/v1/retrieval/nvidia/llama-nemotron-rerank-vl-1b-v2/reranking"
CHAT_URL            = "https://integrate.api.nvidia.com/v1"
EMBED_MODEL  = "nvidia/llama-nemotron-embed-1b-v2"
RERANK_MODEL = "nvidia/llama-nemotron-rerank-vl-1b-v2"
LLM_MODEL    = "nvidia/llama-3.3-nemotron-super-49b-v1.5"
LANCEDB_URI, TABLE = "./lancedb", "colab_demo"
df = df_offline
if HAVE_KEY:
   print("n=== STAGE 2: multimodal ingest via hosted NIMs ===")
   ing = (
       create_ingestor(
           run_mode="inprocess",
           allow_no_gpu=True,
           error_policy="collect",
       )
       .files(DOCS)
       .extract(
           extract_text=True,
           extract_tables=True,
           extract_charts=True,
           extract_infographics=True,
           extract_images=False,
           method="pdfium",
           dpi=200,
           table_output_format="markdown",
           page_elements_invoke_url=PAGE_ELEMENTS_URL,
           ocr_invoke_url=OCR_URL,
           table_structure_invoke_url=TABLE_STRUCT_URL,
           graphic_elements_invoke_url=GRAPHIC_ELEM_URL,
           api_key=API_KEY,
           request_timeout_s=120.0,
           split_config={"text": {"max_tokens": 512, "overlap_tokens": 64}},
       )
       .dedup(content_hash=True, bbox_iou=True, iou_threshold=0.45)
       .embed(
           embedding_endpoint=EMBED_URL,
           model_name=EMBED_MODEL,
           embed_model_name=EMBED_MODEL,
           api_key=API_KEY,
           input_type="passage",
           inference_batch_size=16,
           nim_http_max_concurrent=8,
       )
       .vdb_upload(
           vdb_op="lancedb",
           vdb_kwargs={
               "uri": LANCEDB_URI,
               "table_name": TABLE,
               "overwrite": True,
               "create_index": True,
               "index_type": "IVF_HNSW_SQ",
               "metric": "l2",
           },
       )
   )
   t0 = time.time()
   df = ing.ingest(show_progress=True)
   print(f"ingested in {time.time()-t0:.1f}s -> {df.shape}")
We securely load the NVIDIA API key and define the hosted NIM endpoints for layout detection, OCR, table extraction, graphic analysis, embedding, reranking, and generation. We create a multimodal ingestion pipeline that extracts text, tables, charts, and infographics while applying token-aware chunking and content deduplication. We generate embeddings for the extracted content and upload the resulting vectors and metadata to a LanceDB table.
print("n=== Extraction inspection ===")
for col in ["tables", "charts", "infographics", "images"]:
   if col in df.columns:
       n = int(df[col].apply(lambda v: len(v) if isinstance(v, (list, tuple)) else 0).sum())
       print(f"  {col:<14} {n}")
pages = to_markdown_by_page(df)
print("npages rendered to markdown:", list(pages.keys()))
print("n--- page 1 markdown (first 900 chars) ---n", pages[min(pages)][:900])
full_md = to_markdown(df)
if full_md:
   with open("extracted.md", "w") as f:
       f.write(full_md)
   print("nfull document markdown -> extracted.md")
if HAVE_KEY:
   print("n=== STAGE 3: dense retrieval ===")
   retriever = Retriever(
       run_mode="service",
       top_k=5,
       rerank=False,
       vdb_kwargs={"uri": LANCEDB_URI, "table_name": TABLE},
       embed_kwargs={
           "embedding_endpoint": EMBED_URL,
           "model_name": EMBED_MODEL,
           "embed_model_name": EMBED_MODEL,
           "api_key": API_KEY,
           "input_type": "query",
       },
   )
   QUERIES = [
       "Given their activities, which animal is responsible for the typos in my documents?",
       "What is the most expensive gadget and how much does it cost?",
       "Which animal is at the beach?",
   ]
   def show(hits, label=""):
       print(f"n--- {label} ---")
       for i, h in enumerate(hits, 1):
           meta = h.get("metadata")
           if isinstance(meta, str):
               try: meta = json.loads(meta)
               except Exception: meta = {}
           page = (meta or {}).get("page_number", "?")
           score = h.get("_distance", h.get("rerank_score", ""))
           body = " ".join(str(h.get("text", "")).split())[:180]
           print(f" {i}. p{page} score={score}  {body}")
   show(retriever.query(QUERIES[0]), "single query")
   for q, hits in zip(QUERIES, retriever.queries(QUERIES, top_k=3)):
       show(hits, q[:60])
We inspect the extracted multimodal elements and convert the processed document into page-level and full-document Markdown. We configure a dense retriever that embeds user queries and searches the LanceDB vector index for the most relevant document chunks. We test both individual and batched queries while displaying page numbers, similarity scores, and retrieved text previews.
if HAVE_KEY:
   print("n=== STAGE 4: retrieve + VL rerank ===")
   reranking = Retriever(
       run_mode="service",
       top_k=5,
       rerank=True,
       vdb_kwargs={"uri": LANCEDB_URI, "table_name": TABLE},
       embed_kwargs={
           "embedding_endpoint": EMBED_URL, "model_name": EMBED_MODEL,
           "embed_model_name": EMBED_MODEL, "api_key": API_KEY, "input_type": "query",
       },
       rerank_kwargs={
           "model_name": RERANK_MODEL,
           "invoke_url": RERANK_URL,
           "api_key": API_KEY,
           "refine_factor": 4,
           "batch_size": 16,
       },
   )
   try:
       show(reranking.query(QUERIES[0]), "reranked")
   except Exception as e:
       print("rerank unavailable, dense results stand:", type(e).__name__, str(e)[:160])
if HAVE_KEY:
   print("n=== STAGE 5: filtered retrieval ===")
   try:
       hits = retriever.query(
           "gadget costs",
           top_k=5,
           vdb_kwargs={"where": "text LIKE '%Cost%'"},
       )
       show(hits, "where: text LIKE '%Cost%'")
   except Exception as e:
       print("filter push-down failed:", type(e).__name__, str(e)[:160])
   import lancedb
   tbl = lancedb.connect(LANCEDB_URI).open_table(TABLE)
   print("nrows in LanceDB:", tbl.count_rows())
   print(tbl.to_pandas()[["text"]].head(3).to_string())
We create a vision-language reranking pipeline that retrieves a wider candidate set and reorders the results according to semantic relevance. We also apply a text-based filter to narrow retrieval results to chunks containing specific content from the document. We directly inspect the LanceDB table to verify the number of stored records and examine the indexed text.
if HAVE_KEY:
   print("n=== STAGE 6: RAG answer ===")
   from openai import OpenAI
   client = OpenAI(base_url=CHAT_URL, api_key=API_KEY)
   def rag(question, k=5):
       hits = retriever.query(question, top_k=k)
       ctx = []
       for i, h in enumerate(hits, 1):
           meta = h.get("metadata")
           if isinstance(meta, str):
               try: meta = json.loads(meta)
               except Exception: meta = {}
           ctx.append(f"[{i}] (page {(meta or {}).get('page_number','?')})n{h.get('text','')}")
       prompt = textwrap.dedent(f"""
           Answer the question using ONLY the numbered context below.
           Cite the sources you used as [1], [2], etc. If the context is
           insufficient, say so plainly.
           Context:
           {chr(10).join(ctx)}
           Question: {question}
           """)
       r = client.chat.completions.create(
           model=LLM_MODEL,
           messages=[{"role": "user", "content": prompt}],
           temperature=0.0, max_tokens=512,
       )
       return r.choices[0].message.content, hits
   for q in QUERIES[:2]:
       try:
           ans, _ = rag(q)
           print(f"nQ: {q}nA: {ans}n" + "-" * 70)
       except Exception as e:
           print("generation failed:", type(e).__name__, str(e)[:200])
if HAVE_KEY:
   print("n=== Recall@k check ===")
   GOLD = [
       ("which animal is jumping onto a laptop", "Cat"),
       ("what does the chart show", "Gadgets"),
       ("which animal is at the beach", "Giraffe"),
   ]
   K = 5
   hit_lists = retriever.queries([q for q, _ in GOLD], top_k=K)
   got = sum(
       any(exp.lower() in str(h.get("text", "")).lower() for h in hits)
       for (_, exp), hits in zip(GOLD, hit_lists)
   )
   print(f"recall@{K} = {got}/{len(GOLD)} = {got/len(GOLD):.2f}")
print("nDone. Artifacts: ./lancedb (vector table), ./extracted.md (markdown).")
We combine the retrieved document chunks with a hosted Nemotron language model to generate answers grounded only in the supplied context. We include numbered source references and page metadata so the generated responses remain traceable to the original document. We conclude by calculating recall at k for a small set of expected answers and report the final vector database and Markdown artifacts.
In conclusion, we created a complete multimodal RAG system that transforms structured and unstructured PDF content into searchable, citation-ready knowledge. We used NeMo Retriever to coordinate extraction, deduplication, chunking, embedding, vector database indexing, retrieval, and reranking while keeping the Colab runtime lightweight by delegating model inference to hosted NVIDIA NIM services. We also generated grounded answers with a Nemotron language model and measured retrieval effectiveness with a simple recall-at-k test. By completing this workflow, we established a reusable foundation for building document intelligence applications that process text, tables, charts, and visual elements through a unified retrieval pipeline.
Check out the FULL CODES here. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.
